Checkout Stuck, CPU Calm: Observability That Finds the Unfinished Work
A green server graph can hide delayed orders. Connect real business outcomes to metrics, protected logs and traces, then give each alert an action and an owner.
“Checkout is stuck, ” support reports at 10:01. CPU is only 40%, and the homepage still opens. In this teaching scene, the useful question is not whether the server is green. It is whether customers receive the right outcome and where the unfinished work is waiting.
Part 4 of Engineering for High Volume builds a small evidence chain: a business outcome, an aggregate signal, a specific operation and a controlled response. It does not claim a real incident, personal benchmark or guaranteed diagnosis time.
Define what success means before measuring it
An HTTP 200, completed queue job or “payment page opened” is not proof of a paid order. Define the eligible operation, correct result, timing boundary and exclusions. A proposed checkout SLI might require an accurate result or durable pending receipt within 2 seconds. Payment/fulfilment completion then needs separate freshness objectives; otherwise “pending” can stay green forever.
For the arithmetic below, assume a 99% good-event objective over 30 days and a planning envelope of 3,000,000 eligible attempts. “Bad” is the union of incorrect, failed or too-slow outcomes: count an attempt once even if it is both failed and slow. These are teaching assumptions, not a measured StoreConsole SLO.
Teaching calculation
Result
Planned eligible attempts /30 days
3,000,000
Allowed bad fraction: 1−99%
1%
Planned bad-event budget
30,000
Burst: 440×600
264,000
Bad events: 264,000×2%
5,280
Planned budget consumed: 5,280÷30,000
17.6%
At 440 eligible attempts/s for 10 minutes, 264,000 attempts arrive. If 2% are bad, 5,280 consume 17.6% of the planned 30,000 budget. The bad-rate ratio is 2× the allowed 1%; converting that into time to exhaustion needs a traffic assumption. Google’s SLO alerting guidance motivates multi-window, impact-aware alerts. A fixed 2% is not a universal paging threshold; volume, risk and response urgency matter.
Join the signals without confusing their identities
OpenTelemetry signals connect aggregate metrics, event logs and span-based traces. Use the four golden signals—latency, traffic, errors and saturation—alongside actual business completion. Watch pool/lock waits, eligible-ready queue age, oldest unresolved obligation, storage and memory, not only CPU. Deliberately future-scheduled jobs are not already late.
Evidence
Question
Boundary
Outcome counter
Was the correct result delivered in time?
Eligibility and one-count-per-attempt definition
Structured log
What happened to this operation/attempt?
Scoped access; minimal sensitive fields
Trace
Where did instrumented time go?
Coverage, overlap and sampling limitations
Audit/reconciliation record
What durable business effect actually exists?
Separate authority, retention and recovery controls
A request ID identifies one request; a trace ID links instrumented work; a business operation ID survives relevant retries, while each attempt remains distinguishable. Queue work may continue later in a linked trace. W 3 C Trace Context provides propagation rules, not authentication. Validate/limit untrusted incoming IDs, generate safe internal correlation where appropriate and do not forward sensitive context indiscriminately to partners.
A span is evidence of instrumented time, not automatic root cause. Nested and parallel spans overlap, so adding every duration double-counts time. Normalise timestamps and units, use sound duration measurement and mark deployments/configuration changes. A nearby release is a hypothesis, not proof that rollback is safe.
Use latency distributions and success/failure populations, with counts and rates. Means can help capacity planning but hide tails. Prometheus histogram guidance explains aggregation choices: do not average per-node p95 values into a fleet p95. Use compatible distributions/buckets or another correct method, with known windows.
Collect enough evidence without creating another incident
Structured logs should carry timestamp, service/environment/release, normalised route, outcome/reason, duration/unit and the scoped correlation needed for investigation. Raw paths can contain personal data even without query strings. Internal IDs can still be sensitive; minimise and restrict them. OWASP logging guidance supports excluding secrets and controlling access, integrity, retention and log-injection risk. Do not copy card data, passwords, tokens or customer documents into telemetry.
Request/order/user IDs belong in appropriately protected searchable context when needed, not unbounded metric dimensions. Prometheus label guidance warns about high-cardinality time series; Loki label guidance likewise distinguishes stream labels from detailed searchable fields. A customer ID on every label can exhaust a small backend even with modest request volume.
Set retention by purpose and applicable requirements, including deletion and legal holds. Size ingestion, indexing, queries and recovery from measured volume; there is no universal 2 GB logging node or 30-day retention. Monitor collector drops, exporter failures, buffers, disk and the alert-delivery path. Bound retries/backoff and buffering so telemetry failure does not hang checkout. Required durable audit evidence needs its own explicit policy, not silent sampling/drop.
OpenTelemetry sampling guidance distinguishes early head decisions from later tail decisions. Head sampling cannot guarantee retaining every later error. Tail policies can favour errors/slow traces but need capacity, wait windows and consistent routing; they cannot restore spans already discarded upstream. Record loss/sampling coverage and keep unsampled outcome counters suitable for the SLI. Verify the actual SDK/instrumentation versions, not a blanket claim that every integration is stable.
Make an alert lead to a bounded decision
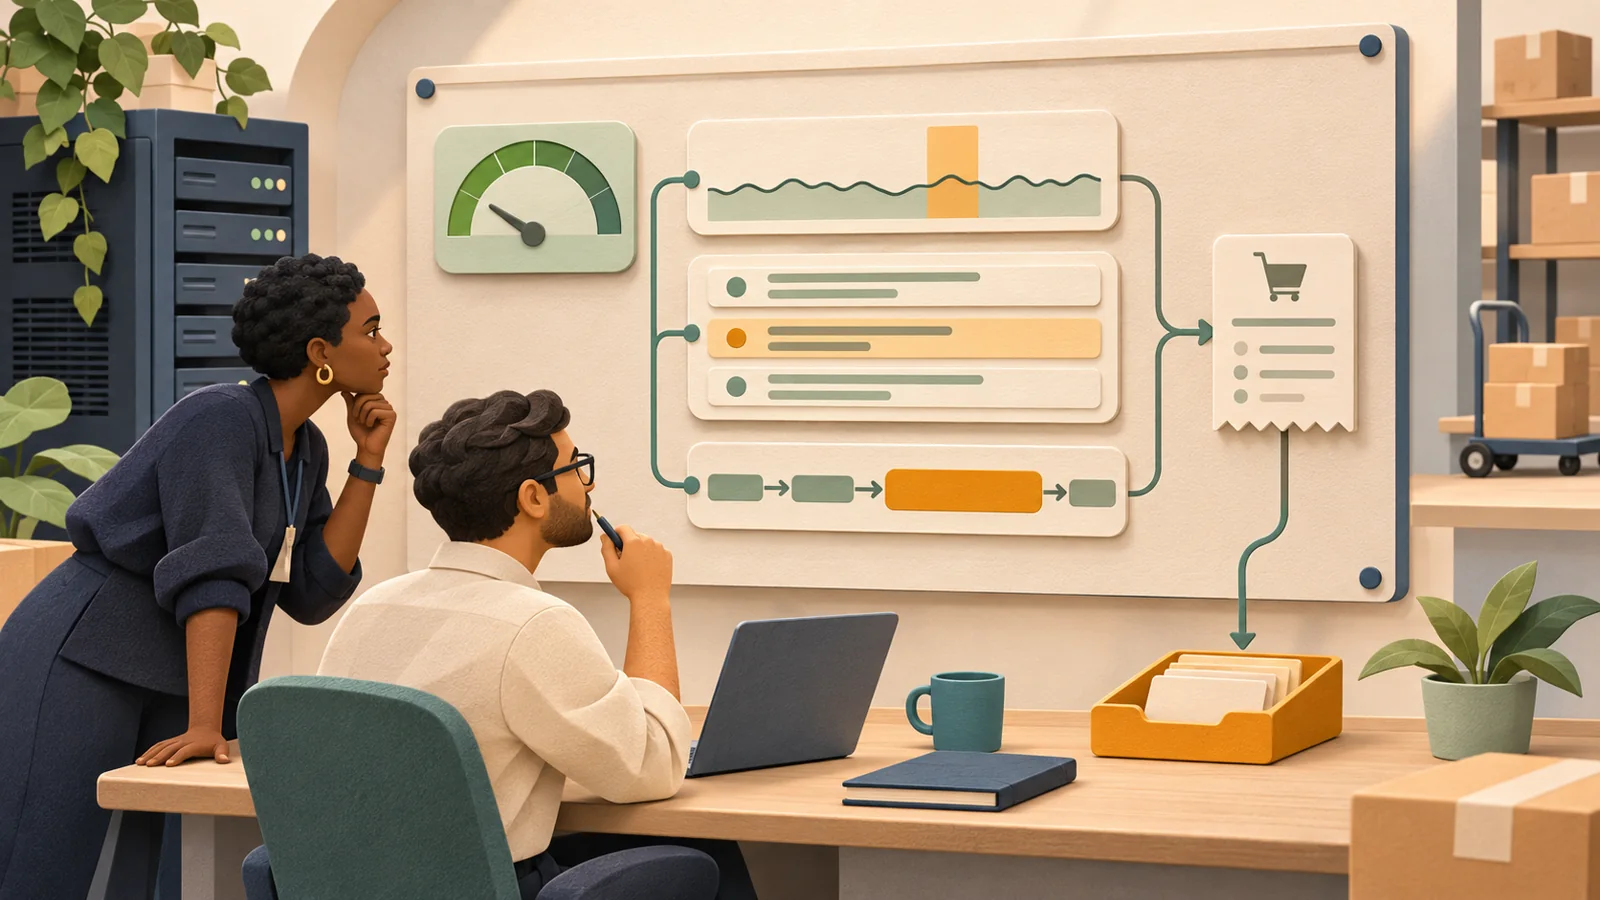
The first screen should show the critical journey’s good/bad volume and latency, then waiting work and resource limits, with drill-downs by scope. Keep it readable on the devices used during incidents. External/synthetic checks and provider evidence complement internal metrics; missing telemetry is not zero errors.
A page needs an owner, affected scope, evidence, runbook and escalation. Combine appropriate short/long windows, minimum traffic where meaningful and severity. Security, data corruption or impending capacity failure may need urgent action before a user-error rate rises. A low-volume money mismatch can be more urgent than a noisy CPU graph.
Verify the affected service and business state, preserve evidence and choose a reversible mitigation. Do not automatically restart a database or roll back every release from the last 15 minutes. Check schema/API compatibility, in-progress payments and already accepted work. If an external result is unknown, query its original reference before repeating the financial action. Reconcile actual outcomes and the recovery backlog after mitigation; a falling error chart alone is not closure.
Teaching investigation flow. Correlation narrows a hypothesis; a durable business record and current permissions determine the safe next action.
Rehearse the investigation and the monitoring failure
In an isolated or explicitly controlled load test, exercise the representative request mix and cold-cache/dependency behaviour. Record offered versus completed work, generator limits, test scope and stop conditions. A CPU guard cannot guarantee that testing never causes an outage. Provider and application charts may differ because of windows, denominators, units or scope; reconcile those definitions before declaring one wrong.
Inject a slow dependency, failed enqueue, delayed callback and exporter outage; test that the alert reaches its owner and that the linked record explains unfinished work without exposing another entity’s data. Keep results, decisions and limitations with the change. Back at 10:01, the evidence should narrow the wait and protect recovery—not turn a calm CPU percentage into a promise that customers are fine.
Reviewed 6 November 2026. Anichur Rahaman, creator of StoreConsole. SLO, traffic and budget figures are teaching examples, not measured service results.



 Software Architecture