Securing and Shipping at Peak Traffic: A Release Plan You Can Defend
A private origin and a blue/green switch are only part of the story. Plan real capacity, compatible data changes, worker handover and a tested recovery path.
At 09:44, an engineer is asked to deploy an email typo fix before a 10:00 ticket sale. The team also sees a burst of login attempts. This is an illustrative scene, not a field report. There are 16 minutes left, but neither a small diff nor two green server icons proves that a release is safe.
The useful question is not “Can we switch versions quickly?” It is “Can customers keep completing the right transaction while old and new components coexist—and can we recover without losing or repeating work?” Sometimes the responsible answer is to defer a cosmetic fix until after the peak.
OWASP Top10:2025 highlights broken access control, security misconfiguration and software supply-chain failures. It is a risk-awareness reference, not a complete security assessment or proof that a firewall fixes those problems. Draw the customer route, administrative route, background connections and outbound integrations before buying another layer.
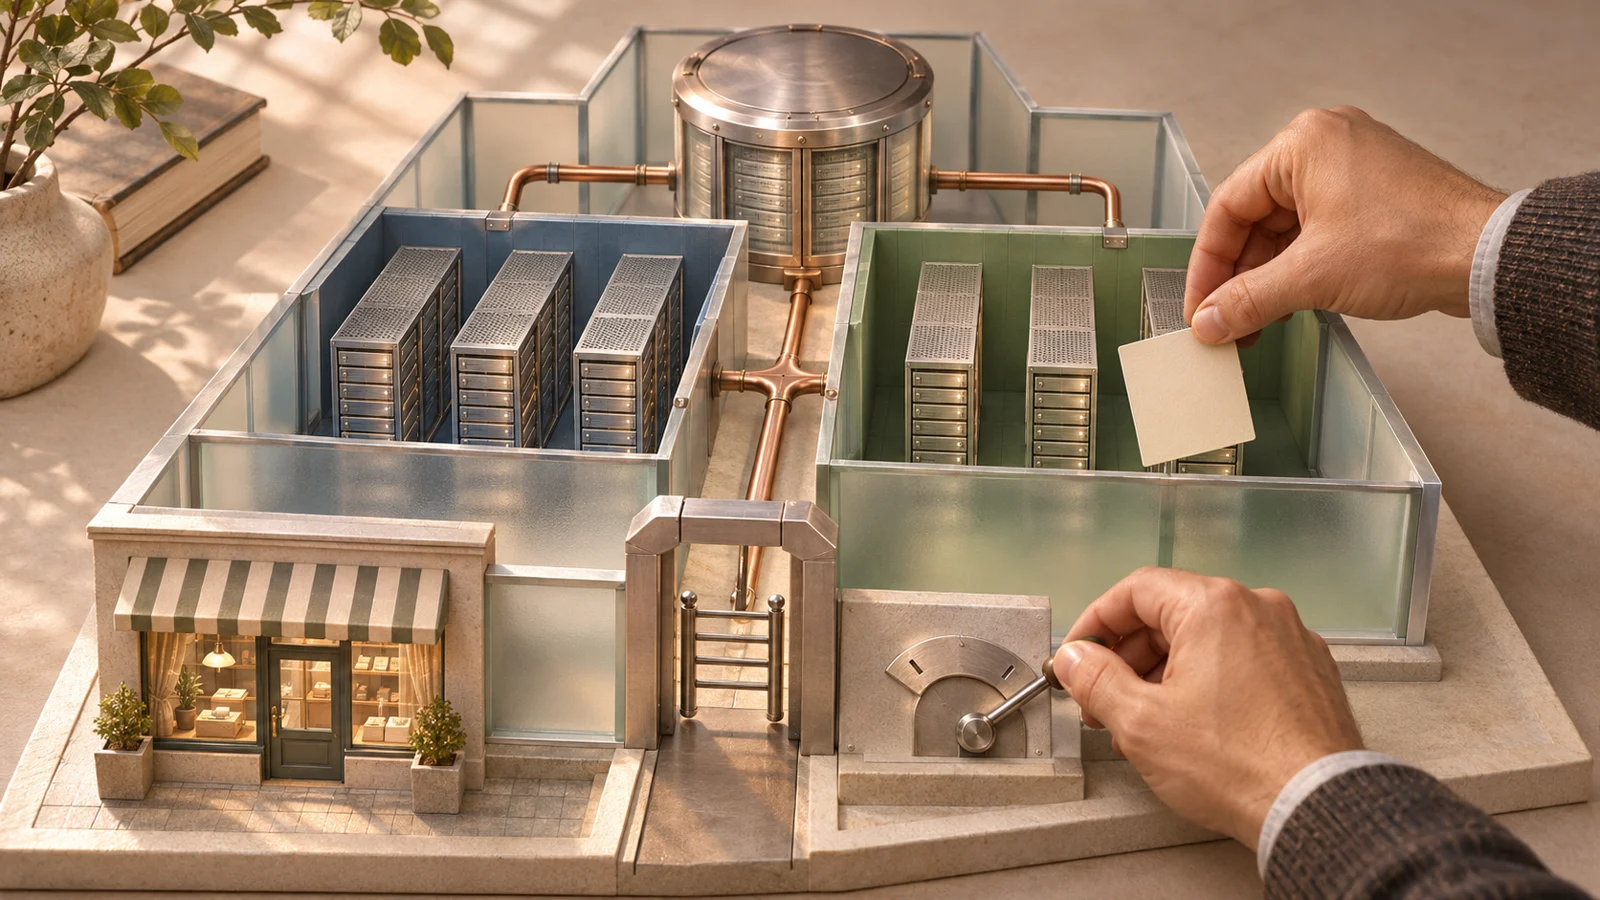
Put appropriate edge protection in front of public web traffic, then restrict the origin’s actual listeners and all alternate addresses, including IPv6. Authenticate the intended edge-to-origin route and validate allowed hostnames. A provider-wide IP allowlist does not identify your own account. For example, Cloudflare’s global origin-pull certificate is shared across accounts; stricter account/hostname binding needs an appropriate configuration, not just the green setting.
Keep database/cache access scoped to authorised workloads and administration behind a controlled access path with strong identity. A private address alone is not authorisation. Segment sibling applications deliberately: a shared service alias resolving to the wrong container is a possible routing/data-exposure failure, not a claimed incident here. Necessary health checks and observability still need narrowly defined access; “workers accept no inbound traffic” is not a universal architecture rule.
Protect the whole route, including ordinary customer sessions
OWASP’s current TLS guidance favours TLS 1.3, with securely configured TLS 1.2 for required compatibility, and disables deprecated protocols. Validate certificates and peer identity on relevant hops. Do not assume that a private subnet makes plaintext safe; document any same-host exception against the actual threat model. Encryption does not replace access control.
A CDN can cache eligible public content and provide configured attack protection, but it does not automatically absorb every flood or make checkout safe to cache. Keep personalised, authenticated, cart, checkout and session-setting responses out of shared caches unless an explicitly safe design proves separation. Test that one visitor cannot receive another’s session or account data.
Tune bot challenges and rate limits with real journeys, accessibility, shared-IP customers and legitimate API/webhook clients in mind. A login burst from a few addresses is a signal to investigate, not proof of a scalper. Apply suitable account/action limits too; an edge does not fix a compromised account. Protect secrets outside images/logs, restrict build/deploy credentials, patch supported dependencies and test recovery of separately protected backups.
Know exactly what is being promoted
Build a versioned artifact in a controlled pipeline, test it in staging and promote the verified artifact rather than rebuilding independently on serving nodes. Record source revision, dependency/build inputs, approval, configuration version and release reference. Keep secrets separate and compare relevant environment differences: identical code does not make staging and production identical.
Docker documents digest-based image identity. Pin the intended registry digest and platform; a multi-platform index and its platform images have different digests. Do not treat every local image ID as the same kind of identifier. Integrity also needs a trusted build/provenance and verification process: a digest can identify a malicious image perfectly. Keep the previous compatible artifact and assets available for the planned recovery window.
Change the schema while both versions still exist
Expand-and-contract means adding a compatible shape, migrating safely, switching use and removing the old shape later. For a phone-to-contact_phone change, first add the new field in a rehearsed migration. Ensure every live writer, worker and integration has the compatible dual-write behaviour before relying on it. A rolling deployment leaves old-only writers alive for a time.
Backfill in bounded, restartable batches with stable progress tracking and concurrency-safe updates. Do not overwrite a newer customer edit with an old snapshot. Reconcile actual old/new values, including null handling, not just total row counts or “new field is not empty”. Watch locks, WAL, replica lag, disk and business latency; pause when your measured safety limits are crossed.
PostgreSQL 18 ALTER TABLE documentation distinguishes rewrite behaviour from locking. A fast add-column operation can still need a lock and wait behind a transaction. Nullable does not mean lock-free. Rehearse the exact statement and workload, use appropriate lock/statement timeouts and have a stop/recovery plan.
Illustrative arithmetic:2,400,000 rows÷5,000 rows per batch=480 batches. At an assumed 2 seconds each, batch processing totals 960 seconds, or 16 minutes. That excludes waits, throttling, retries and verification; it is neither a completion forecast nor proof of no user impact. Switch reads only after convergence is proven. Contract in a later approved window after old web/worker/job/API dependencies and the promised rollback window are gone.
Capacity decides whether a rolling update is safe
Two nodes provide redundancy only if the remaining capacity can carry the required work under the agreed failure conditions. In a teaching example, peak demand is 900 requests/second and one node sustains 550 for the same tested request mix. Drain one of two and capacity is 350 requests/second short. Two green nodes do not make that rollout safe. Three such nodes might leave 1,100 when one is out, but dependency bottlenecks and safety headroom still require testing.
Kubernetes’ rolling-update guidance illustrates availability and surge controls; you need equivalent explicit decisions on any platform. Start a candidate where capacity permits, verify readiness and representative business behaviour, stop new work reaching the node being removed, and allow bounded in-flight work to finish. A health endpoint can pass while checkout is broken. Readiness, graceful termination and actual load-balancer propagation are separate checks.
Do not hide every interruption with proxy retries. NGINX documents special handling of non-idempotent requests. Retrying a payment after an ambiguous response can repeat a side effect unless the complete application/provider contract prevents it. Preserve operation identity, query unknown outcomes and use bounded recovery. Handle long requests, WebSockets and browser asset/version compatibility explicitly. A failed candidate can still affect shared data or downstream services before receiving public traffic.
Workers and recurring work belong in the release plan
You do not normally have to empty the whole queue to replace workers. Stop old processes taking new jobs, let in-flight work finish within a tested grace period and start compatible replacements with supervision. Keep queued payloads and job handlers compatible across the supported version window. A database rollback cannot un-send an email or un-charge a payment.
Laravel 13 queue documentation describes graceful restart, process supervision and timeout/retry relationships. Verify that restart/pause signalling actually works in your configuration; interruption polling can be disabled. Allow enough shutdown time, keep execution timeout below the applicable retry/visibility boundary with margin, and design job effects for duplicate delivery. Do not force-kill and assume the job was never executed.
Coordinate scheduler ownership or shared locking before a version switch. Laravel’s scheduling documentation describes single-server and overlap controls with shared-cache requirements. Starting a scheduler “last” alone does not prevent duplicate work, and one scheduler process does not make side effects exactly-once. Monitor missed runs, stale locks and long-running/sub-minute tasks; use operation-level deduplication where needed.
A traffic rollback is not a data rollback
Blue/green keeps an active version and a candidate alongside each other and changes routing after acceptance checks. The practical switch includes configuration validation, readiness, propagation and draining; no universal one-second rollback is promised. Retain the old assets needed by open browser sessions and confirm both versions can use the shared session/cache/API contracts.
Before switching, write the failure decision: which business/error/latency/queue-age indicators stop promotion, who decides, which version remains compatible, and how data changes or external effects will be handled. Define a measured observation window. A 20% canary or five-minute soak is not universally enough; important low-volume journeys may not occur in it.
A destructive schema change may make the old binary unusable. Reverting code cannot undo a completed refund, reverse every backfill safely or recover dropped data. Choose a rehearsed forward repair, controlled compatibility rollback or data recovery procedure as appropriate. A fresh dump is not proof of a recoverable business; see the recovery-testing guide. A production database restore can lose later legitimate transactions and needs reconciliation.
Both versions can share data and external effects. Switching traffic does not reverse those effects or guarantee availability.
The go/no-go decision before the sale
Use the table as an evidence checklist, not a guarantee. Run representative authorised end-to-end tests with safe payment/email/shipment handling, compare business outcomes as well as HTTP status, and keep a named operator and escalation route available. Perform exposure tests only against infrastructure you are authorised to test. Redact secrets from evidence rather than copying them into a release ticket.
At 09:44, the typo fix can wait if compatibility, capacity or recovery evidence is incomplete. A genuinely urgent security fix needs an explicit risk decision and a rehearsed path, not an automatic freeze exemption. Security layers and deployment techniques are useful because they make those decisions testable. “Zero downtime” is an objective to measure against a stated scope, not a property granted by two servers or a colour switch.
Unknown external effect, duplicate or missed recurring work
Recovery/acceptance
Named decision owner, business checks, compatible recovery
No recoverable state or no way to reconcile side effects
Reviewed 5 November 2026. Anichur Rahaman is the creator of StoreConsole. Scenes, rates and timing are teaching examples, not benchmarks or claims about an audited production topology.



 Infrastructure & Scaling