Modernising Legacy Business Software Without Losing the Rules That Matter
A new interface can hide an old business mistake. Discover the real risks, preserve the right rules and move one capability with clear data ownership.
Penulis
Anichur Rahaman
3 bulan yang lalu9 menit baca118 tampilan
The new returns screen looks better. Then a test refund is USD 60 while the old invoice supports USD 54. Someone had rebuilt the product price but missed how the original order discount was allocated. This is a teaching example, not a customer case. The difficult part of modernisation is often the rule nobody thought to mention.
The aim is not to preserve every old behaviour or replace every old component. It is to make the business safer to operate and change. Start with evidence about today’s risk, agree the intended rules, then transfer a bounded responsibility without creating two competing truths.
Age is not the same as risk
An older, supported, tested system may be easier to change safely than a recent undocumented one. Ask what you cannot currently do reliably: restore an order, correct an invoice, remove an employee’s access, reconcile a supplier payment or release without calling one particular contractor. These are capabilities to investigate, not proof that every older system needs replacement.
Check vendor support against the exact runtime, framework, plugins and deployment you run. PHP’s current support table is one example: as reviewed on 5 November 2026, PHP 8.2 has security support through 31 December 2026, although active support has ended. “Not receiving ordinary fixes”, “unsupported upstream” and “covered by a paid vendor arrangement” are different facts. A supported runtime also does not certify the application’s security.
Build a risk register the team can act on
Bring operations, finance and the people who maintain the system together. For each item in the table, record the failure scenario, evidence, affected process/data, current controls, impact, estimated likelihood/time horizon, confidence, owner and next action. “Unknown” deserves an investigation, not an invented likelihood. A confirmed active compromise may require containment now, not a place on next quarter’s roadmap.
NIST’s risk-assessment guidance supports considering threats, vulnerabilities, likelihood, impact and uncertainty. A workshop can use consistent qualitative ratings or a simple 1–5 triage scale, but multiplying two ordinal scores does not produce a probability or a monetary loss. A high-colour heat-map cell cannot predict the next incident. No universal 15-point threshold decides what every business must fix this quarter.
Risk to investigate
Evidence to inspect
A useful next action
Support exposure
Exact versions, vendor dates and deployed patches
Owner-approved upgrade/support plan
Key-person dependence
Can a second person restore and release?
Pair a real rehearsal with a runbook
Weak change tests
Critical successful and failed journeys
Capture intended rules and regressions
Unbounded shared writes
Scripts, tables, triggers and data owners
Define one owner and a controlled seam
Security/control gaps
Credentials, scopes, sessions and denied actions
Contain exposure; verify real controls
Conflicting data
Record identifiers, balances and source ownership
Reconcile actual values and define authority
Fragile integration
Lag, retries, unknown effects and failure alerts
Add accountable bounded recovery
Capacity ceiling
Measured waits under representative demand
Fix the demonstrated constraint
Privacy/audit gaps
Access, event evidence and applicable retention
Document scope, ownership and retrieval
Exit/licence constraints
Export completeness, attachments and contract
Rehearse usable export and exit dependencies
Choose a treatment, not a fashionable architecture
Retain and operate a healthy capability where the current risk is acceptable. Upgrade a supported path, refactor a difficult boundary, replace a capability after fit-gap testing, or retire work no longer needed. A re-platform can improve supportability while carrying the same business defects across. Buying a standard module is not proof that its tax, stock, payroll, export and integration rules fit your business.
A bounded full replacement can be reasonable for a small, well-understood system with a tested cutover. A large rewrite can accumulate hidden-rule and delayed-feedback risk. Neither “rewrites usually fail” nor “incremental always wins” is a defensible universal statistic. Compare coexistence cost, operating deadlines, team capacity, data access and recovery options before choosing.
Recover the meaning behind the old screen
Use representative orders, failed payments, returns, partial deliveries, rounding, timezones and permission boundaries as examples. Characterisation tests record existing behaviour so changes become visible; the business owner must distinguish a valid rule from an existing bug. An intentional correction needs an agreed expected result, not a permanent promise to reproduce the bug.
In our illustrative order, two units cost USD 50 each before tax. AUSD 10 order discount is allocated equally, there is no shipping or other charge, and an assumed 20% tax applies to the discounted amount. Net 90 + tax 18 = paid 108. Under the agreed proportional-return rule, one unit returns net 45 + tax 9 =USD 54. Refunding full price plus tax would be USD 60,USD 6 too much under those assumptions. Actual allocation, rounding and tax obligations must be verified; this is not a universal return formula.
A shadow comparison should compare safe calculations or suitably protected fixtures. Do not send the same live refund, stock movement, payroll run or courier booking to both systems. Disable external effects before replay. Passing the same input twice is not safe merely because the screen is called “test”.
Move a capability with one authoritative writer
The Strangler Fig pattern replaces bounded responsibilities gradually while the rest of the system continues operating. A routing facade is one possible seam, not an instruction to create microservices. A modular application, an adapter or an existing integration point may be enough. The facade itself needs availability, performance and security review; a new gateway can become another failure point.
Choose a boundary with useful value, understood dependencies and a recoverable handover. “Stock” or “orders” can be tightly coupled and risky first choices. Define identifiers, ownership, field meaning, state transitions and which system may write each business fact at each stage. An anti-corruption layer translates models; it is not an access-control exemption.
Authorisation must remain enforced on the actual record and action through every route. Preserve tenant/outlet scope, restricted fields, audit attribution and service identity in old and new paths. A feature flag selects a route; it does not grant permission or make reversing new data automatic.
Synchronisation needs recovery semantics
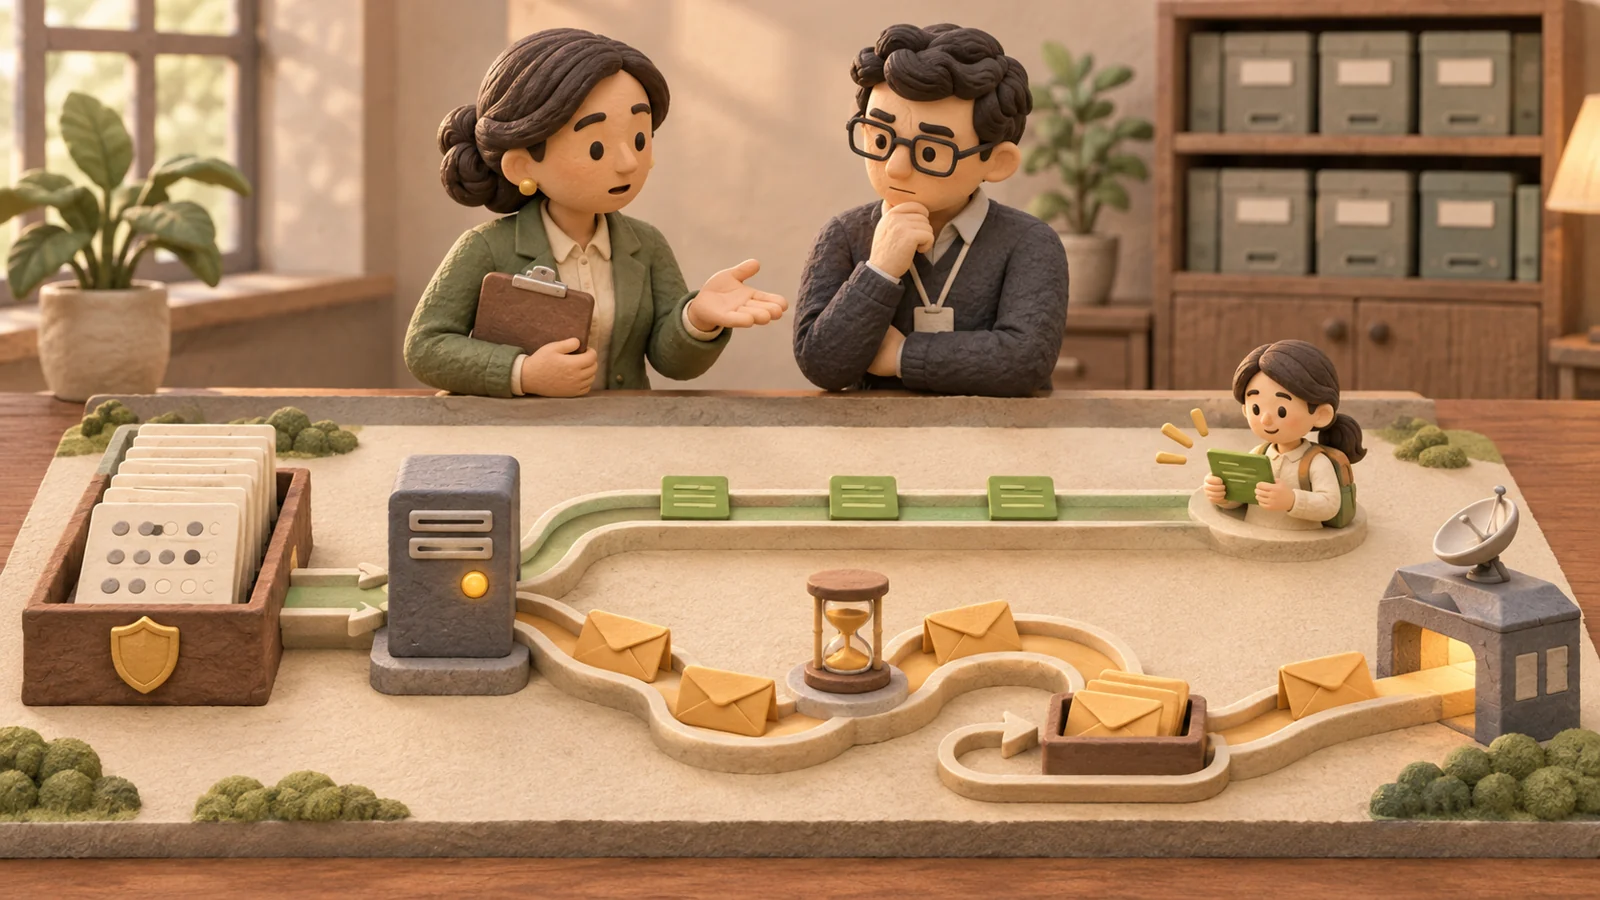
If you can change the legacy transaction, a transactional outbox can commit a business change and its publication intent together. The relay may deliver twice, late or out of the expected order; consumers need stable event/operation identity, safe duplicate handling, version/ordering rules and reconciliation. An outbox does not make two databases or an external refund one atomic transaction.
Where an outbox cannot be added, assess supported APIs, exports or change-data capture with explicit constraints. Capturing table changes does not automatically reveal the business meaning of every update. Define initial snapshot and catch-up boundaries, deletes, historic corrections, schema changes and downtime. Monitor lag and failed messages; use bounded retry/backoff, isolate poison messages and assign unresolved work rather than retrying forever. Keep sensitive payloads within an authorised boundary.
Prove the handover and the way back
Before changing write authority, reconcile identifiers, actual field values, balances, states and external references at a defined checkpoint—not just row totals. Test the real database engine and production-like constraints. Verify permission denials, duplicate/out-of-order events, interrupted imports, missing dependencies and restored backups. Keep migration/reference-data scripts repeatable without overwriting user choices.
During cutover, stop or deliberately coordinate old writes, drain/capture changes to the agreed boundary, catch up, validate, then enable the new authority. Watch end-to-end business outcomes and exceptions in a limited, observable cohort where that is safe. A new screen returning 200 does not prove its ledger, stock and payment effects agree. Compare baseline and new latency, errors and manual reconciliation effort as well as business outcomes. Give users readable, appropriately localised failures without exposing internals; an unknown external result must not become a false failure followed by a duplicate action.
If the new system has accepted writes, routing back may strand them in the new store or replay effects. Recovery might need a tested reverse sync, forward repair or a controlled pause/reconciliation—not just a flag flip. Define the compatible data state, decision owner, stop conditions and how already-completed external actions are handled. See the safe-deployment guide for the code-versus-data rollback boundary.
Do not duplicate live payments, refunds or stock effects in a parallel run. A route selector is not a data recovery mechanism.
Retire the dependency, not just the login page
Find old reports, scheduled jobs, webhooks, supplier scripts, support tools, credentials, licences and archive readers before decommissioning. Keep only data and software needed for agreed operational, contractual and applicable legal purposes, with controlled access and a verified retrieval path. Do not keep all personal data forever or delete all financial evidence automatically on request. Confirm applicable retention/privacy duties and vendor exit terms.
StoreConsole may be a candidate in a fit-gap exercise. Validate the exact version, enabled modules, integration contracts, migration tooling, permissions and recovery in a pilot; do not infer independent adoptability or complete controls from a module list. The existing overview below is a demonstration, not certification that every module logs every action, enforces two-factor sign-in or closes migration risks on day one.
Existing interface overview (0:47). Demonstration only; verify version-specific permissions, sign-in and audit coverage in your pilot.
Your first deliverable is a safer decision
Agree a short discovery window rather than promise every project a fixed 30-day transformation. Produce a risk register with owners, evidence of a recoverable system, examples of critical rules and a bounded pilot plan with acceptance and recovery criteria. Contain urgent exposure first. The first migrated capability may come later if dependencies or data quality are not yet understood.
Return to the USD 54 test refund. The valuable result is not that the new software now matches the old screen. It is that the intended discount rule is written, the calculation is checked, only one system can issue the refund, and an authorised person can trace its actual outcome. That is a stronger foundation for the next change.
Reviewed 5 November 2026. Anichur Rahaman is the creator of StoreConsole. The refund and migration scenarios are illustrative; no customer outcome or universal timetable is claimed.




 Software Architecture