Scaling Self-Hosted Commerce: From Daily Orders to a Tested Capacity Plan
100,000 orders a day is a business goal, not a server specification. Translate traffic into peak work, remove the measured bottleneck and test failure capacity.
Auteur
Anichur Rahaman
il y a 4 mois8 min de lecture150 vues
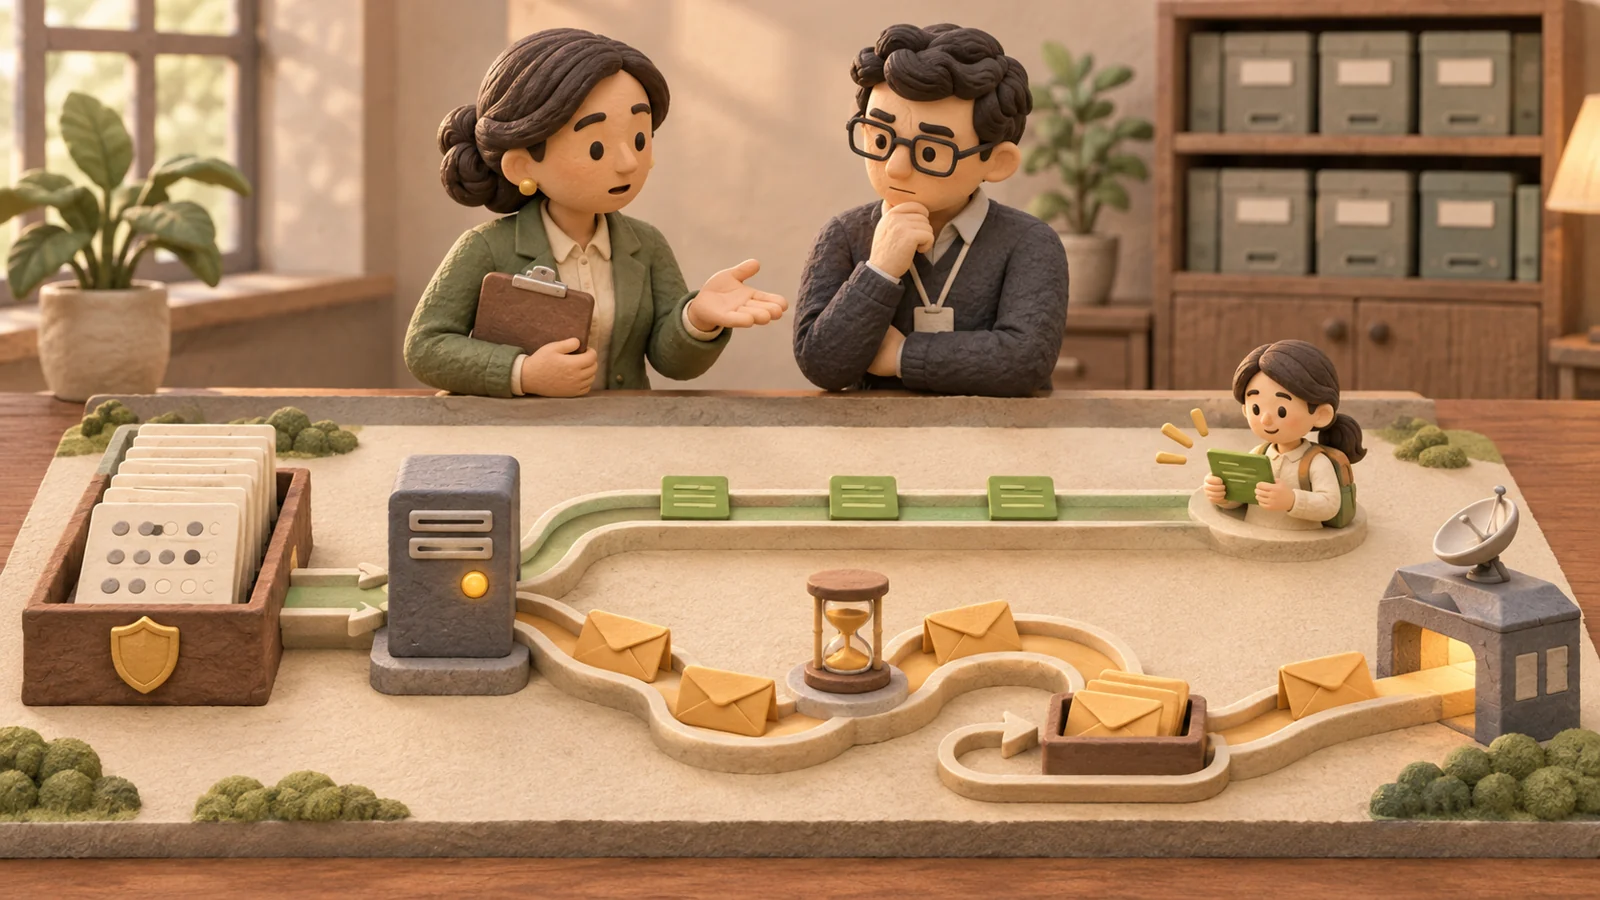
A shop’s daily orders have doubled, so the owner asks for a server twice as large. But checkout slows only when a product import and a finance report overlap the lunchtime rush. More hardware might help; it might also hide the wrong query, an exhausted connection pool or jobs competing for memory. This is a teaching scenario, not an observed customer case.
A useful roadmap connects a business promise to measured work. The same 100,000 orders/day can mean a steady global business or a short, concentrated sale. There is no universal order count at which you must buy a particular CPU, separate Redis or operate a fleet.
First translate orders into work
Accepted orders, attempted checkouts, visitors, dynamic requests, database transactions and background jobs are different quantities. Include unsuccessful buyers, repeated requests, imports, webhooks, reports and expensive product searches in the workload. Static assets answered at the CDN are a separate path. Conversion rate and requests per visit can change long before orders do.
Here is an illustrative model, not a benchmark.100,000 accepted orders/day average about 1.16 orders/second over 86,400 seconds. Assume the whole day’s customer traffic produces 20 dynamic origin requests per accepted order, including browsing by people who never buy. That ratio gives 2,000,000 origin requests/day, about 23.15 requests/second—not the size of each individual buyer’s journey.
If 15% of those requests arrive within 15 minutes, 300,000÷900≈333.33 requests/second during that window. One-second bursts can be higher. If the same stable interval has a mean request residence time of 0.24 seconds, mean outstanding work is roughly 333.33×0.24≈80 requests. This is not 80 CPU cores, PHP children or database connections. Use matching boundaries and mean values; p95 latency cannot replace the mean in this calculation.
The ratio and burst are assumptions to replace with measured traffic. Static assets, background jobs and resource limits need their own model.
Measure the promise and the bottleneck together
Define a business journey: can a shopper reserve the correct variant, obtain the right total, complete the chosen payment flow and receive a durable order reference? Set latency, error and freshness objectives with the business. There is no universal 800 ms checkout or 60% database-CPU pass mark. A fast error page is not a successful purchase.
Measure route-specific p95/p99 latency, errors/timeouts and completed business outcomes alongside incoming demand and accepted throughput. Include failed attempts in the appropriate denominator. Add CPU throttling, process memory/OOM, storage latency/free space, database connection waits/locks/slow-query contribution and queue processing rates, retries and oldest ready-job age. Delayed scheduled jobs are not all late work. Correlate a slow checkout with the resource or dependency that actually waited.
Keep a small installation simple—but operated
One host can be a sensible starting point when its measured workload and downtime risk allow it. So can a managed database from the outset. Neither is mandatory. Budget memory, CPU, storage, backups and operational access for every process, not just the web server. Supervise workers and recurring work; a process launched in a temporary shell is not reliable operations.
PHP-FPM documents its concurrent-request process limits. Set them from measured per-process memory, shared overhead, CPU and downstream capacity; more children can exhaust RAM or database connections. OPcache avoids repeated compilation, but preloading has its own lifecycle and is not a guaranteed 50% speedup. Verify enabled behaviour, memory use and release invalidation. Profile repeated queries and request-time work before adding a cache that can become stale or leak scope.
Separate work when contention earns the complexity
If imports, images, reports or AI jobs repeatedly harm checkout, isolate their resource budgets or move them to a separate worker pool/host. Give critical work capacity and bounded retries; priority alone cannot pre-empt a long job already occupying the only worker. Some checkout decisions must remain consistent before acceptance. Moving work to a queue does not remove that business requirement; a deliberate pending state is different from falsely reporting success.
Separating the database can improve resource isolation, but adds network, security, backup and monitoring responsibilities. A cache/session/queue service also needs deliberate persistence, eviction and availability policies for its actual uses. Laravel documents supported scheduling and coordination options; neither a 512 MB scheduler floor nor one long-lived process is a universal cure. Choose the supported execution mode and prevent unintended duplicate recurring work.
Scale the web tier without moving the bottleneck
Multiple web nodes need shared or appropriately replicated session state, durable uploads and compatible release/configuration. Do not store the only copy of business data on a disposable node. Cache only eligible responses with keys covering host/tenant, language and other representation dimensions. Keep private/session-setting responses out of shared caches unless isolation is proven. A cache miss or stampede still needs controlled rebuild capacity.
PgBouncer’s pooling modes have different semantics. Transaction pooling can reduce backend connection pressure, but requires application compatibility with session features and prepared-statement configuration. It does not create more database execution capacity. Budget connections across web, workers, reporting, migrations and administration; measure pool wait and database saturation before raising limits.
A replica can serve suitable stale-tolerant reads, not every current stock/payment decision. PostgreSQL streaming replication is asynchronous by default and can lag; heavy standby queries may conflict with recovery, and replication still costs resources. A read replica is not automatically a safe failover or independent backup. Scale rendering, search or analytics separately only when their measured demands and operating costs justify it. Server rendering can be on the live request path; it is not automatically background work.
Load-test the arrivals, the state and the failure
Use production-like data size, indexes, realistic popular variants, cache states, third-party delays and background work in an authorised test environment. Start small, raise demand, sustain it and test bursts with explicit stop conditions. Protect personal data and prevent real charges, customer mail and shipments. Record build/configuration and what the test did not cover.
Grafana k6 distinguishes open and closed load models. A fixed-user test can send less work as responses slow; that may not represent a flash-sale arrival stream. When using arrival-rate tests, provision the generator and inspect dropped iterations and actual request metrics. An iteration is a scripted journey, not necessarily one HTTP request or one order. Report attempted arrivals, achieved throughput, outcomes and waiting work together, not just a good latency percentile after load was dropped.
Test the intended degraded state: one web node unavailable, a slow provider, a cold cache or a worker restart. Two nodes do not provide enough failover capacity if one cannot carry the required load. Adding web processes can make database contention worse. Change one justified constraint, rerun the same meaningful test and keep the comparison; do not claim a universal 100,000-order certification from a home-page test.
Growth also changes recovery and release risk
Let the business choose acceptable recoverable data loss and service recovery time—RPO and RTO—from actual impact, not an order-count stage. A nightly scheduled dump alone does not promise at most 24 hours of lost data if jobs fail, archives are incomplete or the backup is inconsistent. Verify the recoverable point and a full business restore. Replication can repeat deletion; it does not replace protected retention.
Keep compatible releases, bounded graceful handover and a rehearsed recovery decision. Blue/green routing cannot reverse a destructive migration or a completed payment. Do not clear shared sessions, locks or an active release’s files indiscriminately. See the secure-deployment guide and recovery-testing guide for those controls. The existing short demonstration below shows an interface, not proof of recovery for your environment.
Existing backup-interface demonstration (0:46). It does not establish your recoverable data point, full service recovery time or installed capabilities.
Choose the next step from evidence
Use the roadmap table as decision gates, not fixed order bands. Estimate total operating cost: compute, storage/IO, replicas, media/egress, monitoring, backup restores, standby capacity and engineering/on-call time. A cheaper server with an untested failure path may be expensive to operate. More components also create more versions, credentials and recovery procedures to maintain.
For the shop in our opening scene, first establish whether the report, import, connection waits or another dependency explains the lunchtime slowdown. Isolate the proven contention, rerun the same mixed journey and verify that order, stock and payment outcomes still agree. The next purchase should follow that evidence—not a promise that one machine size serves every shop at a given daily order count.
For StoreConsole, consult the requirements and installation documentation for the supported baseline, then validate the actual modules, extensions and operating setup you enable. A supported minimum is not a capacity benchmark. Keep the test evidence and a named owner for the next review.
Decision stage
Reason to change
Evidence before accepting
Simple operated runtime
Current workload fits; failure exposure is understood
Mixed-journey test, monitored limits and restored backup
Resource separation improves the same test; costs/ownership covered
Add redundancy and scale-out
Availability or measured capacity requires more nodes
Shared state and degraded-capacity/release tests pass
Specialise operations
Search/analytics/AI/data growth has a distinct constraint
Consistency, lag, retention, total cost and recovery remain acceptable
Reviewed 5 November 2026. Anichur Rahaman is the creator of StoreConsole. Rates and scenarios are illustrative; no hardware tier or capacity guarantee is implied.



 Software Architecture