Ready Before the Spike: A Capacity Plan for the Whole Request Path
Adding an app instance is not the same as serving another checkout. Budget readiness time, test the constrained tier and keep spare capacity for failure.
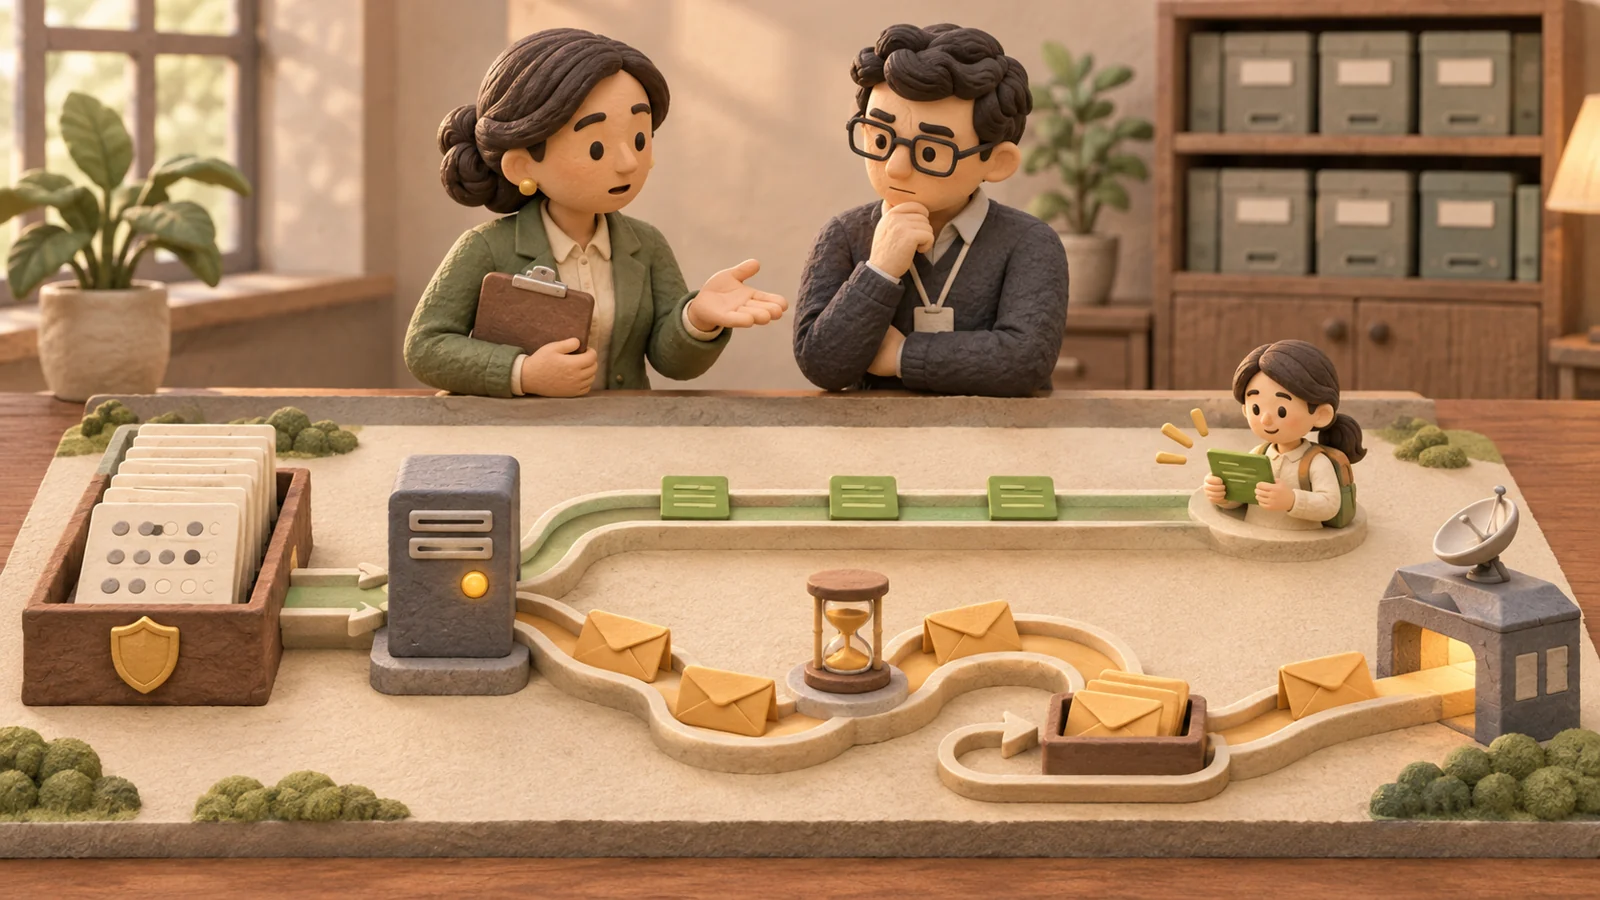
At midnight a scheduled promotion begins. Origin demand steps from 20 to 440 requests per second while the team waits for its scaling rule to add capacity. A machine eventually starts, but image pull, application boot, registration and cache warmup still stand between “running” and a useful checkout. This is an illustrative scenario, not a reported incident or a StoreConsole benchmark.
Predictable demand gives you time to prepare; it does not guarantee that more machines will help. The plan must connect the arrival pattern, the actual request paths, each shared constraint and the time to become ready. This is part 1 of Engineering for High Volume, covering the edge-to-application path.
Budget time to useful capacity, not time to a new machine
Reactive scaling is a control loop: observe a signal, evaluate it, request capacity, start the workload and admit it to traffic. Warm pools or fast processes can respond quickly; slow images, quotas or cold dependencies can respond slowly. There is no universal one-to-three-minute floor or a single cooldown that applies to every policy.
AWS documents distinct step/simple scaling and warmup behaviour. Read the actual policy, metric period, evaluation and scale-in rules. A default described for simple scaling is not a universal delay before every target-tracking scale-out. Measure the critical path in your own environment, including failed provisioning and readiness.
For a planning illustration only, assume sequential detection/control 60 seconds, provisioning 90, registration/health 30 and warmup 30:210 seconds total, or 3 minutes 30 seconds. Stages can overlap in reality. Schedule extra capacity far enough ahead for the observed slow case plus a justified buffer; a running VM count alone does not demonstrate readiness.
Illustrative serial stage
Seconds
Cumulative seconds
Detection/control
60
60
Provisioning
90
150
Registration/health
30
180
Warmup
30
210
Use scheduled or predictive preparation where the event is known, with reactive rules for remaining variation and a declared maximum spend/capacity. Pre-scaling has cost and can fail too. Verify quotas, instance availability and dependencies; keep admission control or a truthful waiting experience for demand beyond tested capacity.
Draw the paths that really reach the origin
Separate cached static assets, public-page hits, dynamic renders, API calls, checkout writes and background jobs. Edge requests, origin requests, users and orders are not interchangeable units. A Next.js page may call an API; a built-in monolith may render through an internal SSR service; some API calls bypass SSR. Do not force every request through a fictional single chain.
Cache immutable assets and genuinely shareable responses using an explicit host/locale/variant policy. Personal accounts, carts, permission-dependent content and responses that set sessions need appropriate bypass or private handling. A page that looks public can still contain personalised data. Test warm and cold caches, invalidation, stampedes and actual cache-hit ratios.
WAF/rate controls and a load balancer also have limits: connections, TLS, bandwidth, registration, quotas and upstream health. A managed service is not automatically unlimited or never the bottleneck. AWS ALB capacity reservation is one provider-specific option for sudden events; estimate and verify it for the actual workload, rather than copying an old capacity-doubling claim.
A health check proves only what it tests. Confirm readiness with dependency-aware probes and representative journeys without making an unhealthy shared service trigger removal of all otherwise useful nodes. Test connection draining, propagation and grace periods; draining reduces disruption but does not promise invisible scaling or repair an already failed request.
Make application instances interchangeable without losing state
Sessions, uploads, job ownership, locks and mutable business state must remain available when an instance disappears. A suitable shared database/session store or durable shared/object storage can help; Redis and S 3 are options, not mandatory answers for every deployment. Local immutable caches can be legitimate. Shared coordination and invalidation have different consistency needs from expendable local cache entries.
Next.js self-hosting guidance describes multi-instance cache coordination and build/version concerns. Deploy compatible artifacts and coordinate invalidation, identity/secrets and generated assets. A shared cache store is not by itself proof that every cache type, tag or in-flight version is safe.
Coordinate scheduled work and prevent duplicate business effects. Laravel’s scheduler documentation describes shared atomic-lock single-server scheduling. Locks, expiry/failover and unique operation identity still need failure tests; merely running cron on one node is not a complete exactly-once design.
Align body/time limits and upload behaviour across the actual proxy/application path, not every possible service. Keep a node failure from losing an accepted upload or payment result. Recheck tenant/record permissions in the authoritative service; scaling out does not grant new authority.
Measure SSR and FPM as workloads, not as host CPU averages
CPU-bound JavaScript on a Node event loop can saturate while other host cores remain idle. That does not mean a Node process can never use other cores: native work, background runtime activity and worker threads change the picture. Measure per-process CPU, event-loop delay, memory/GC, I/O and backend waits before choosing more processes, a different render/cache strategy or faster code.
For PHP-FPM, the official pool settings bound concurrent requests and control process lifecycle. A separate steady-state example with 200 requests/second starting worker execution and mean worker-occupied time 0.15 seconds implies about 30 occupied workers on average. That does not prescribe 60 children, CPU cores or database connections, and p95 cannot replace the mean in that arithmetic.
If an illustrative incremental/private-memory budget is 100 MiB per worker, 60 workers require 6,000 MiB≈5.86 GiB before other services, OS and shared-memory allowances. Do not sum shared OPcache repeatedly as private memory. Measure real peaks and downstream connection/CPU limits. More FPM concurrency can overload the database rather than raise useful throughput.
Warm the appropriate process mode and caches with representative safe requests. OPcache settings that disable timestamp checks need a release procedure that refreshes the serving processes; do not present one copied setting or CLI reset as universal deployment safety. Processes and containers can also have long startup/warmup, so seconds-level scaling must be measured.
Count capacity after a failure, then test the shared ceiling
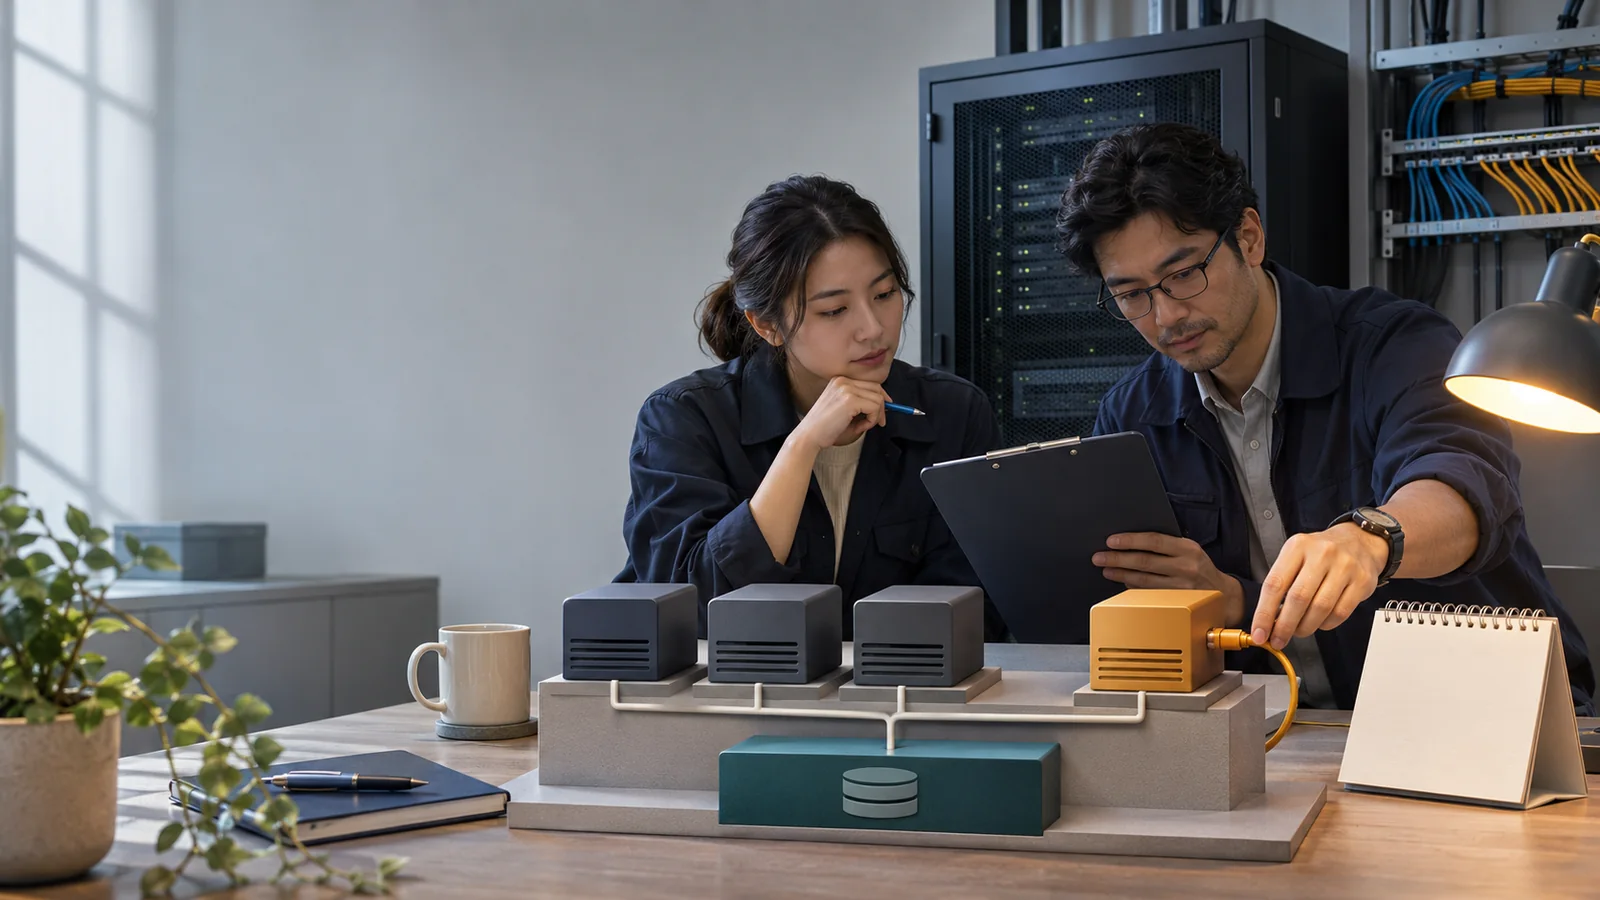
Assume, solely for this planning table, a comparable application instance can sustain 220 origin requests/second for the representative mix at the chosen service objective. Peak demand is 440. Multiplication is a provisional budget, not a claim of measured linear scaling. The table removes one instance, not a whole host or availability zone.
Three instances nominally give 660; after losing one they give 440, exactly the peak with no spare margin. Four give 880 nominally and 660 after one is removed, 1.5 times the target. Colocating them on one machine does not provide four independent failure domains. Test losing the actual host/zone you intend to tolerate.
Instances
Nominal req/s
After one lost req/s
Comparison to 440 peak
2
440
220
220 below peak after loss
3
660
440
440 matches peak, no reserve
4
880
660
660 leaves provisional headroom
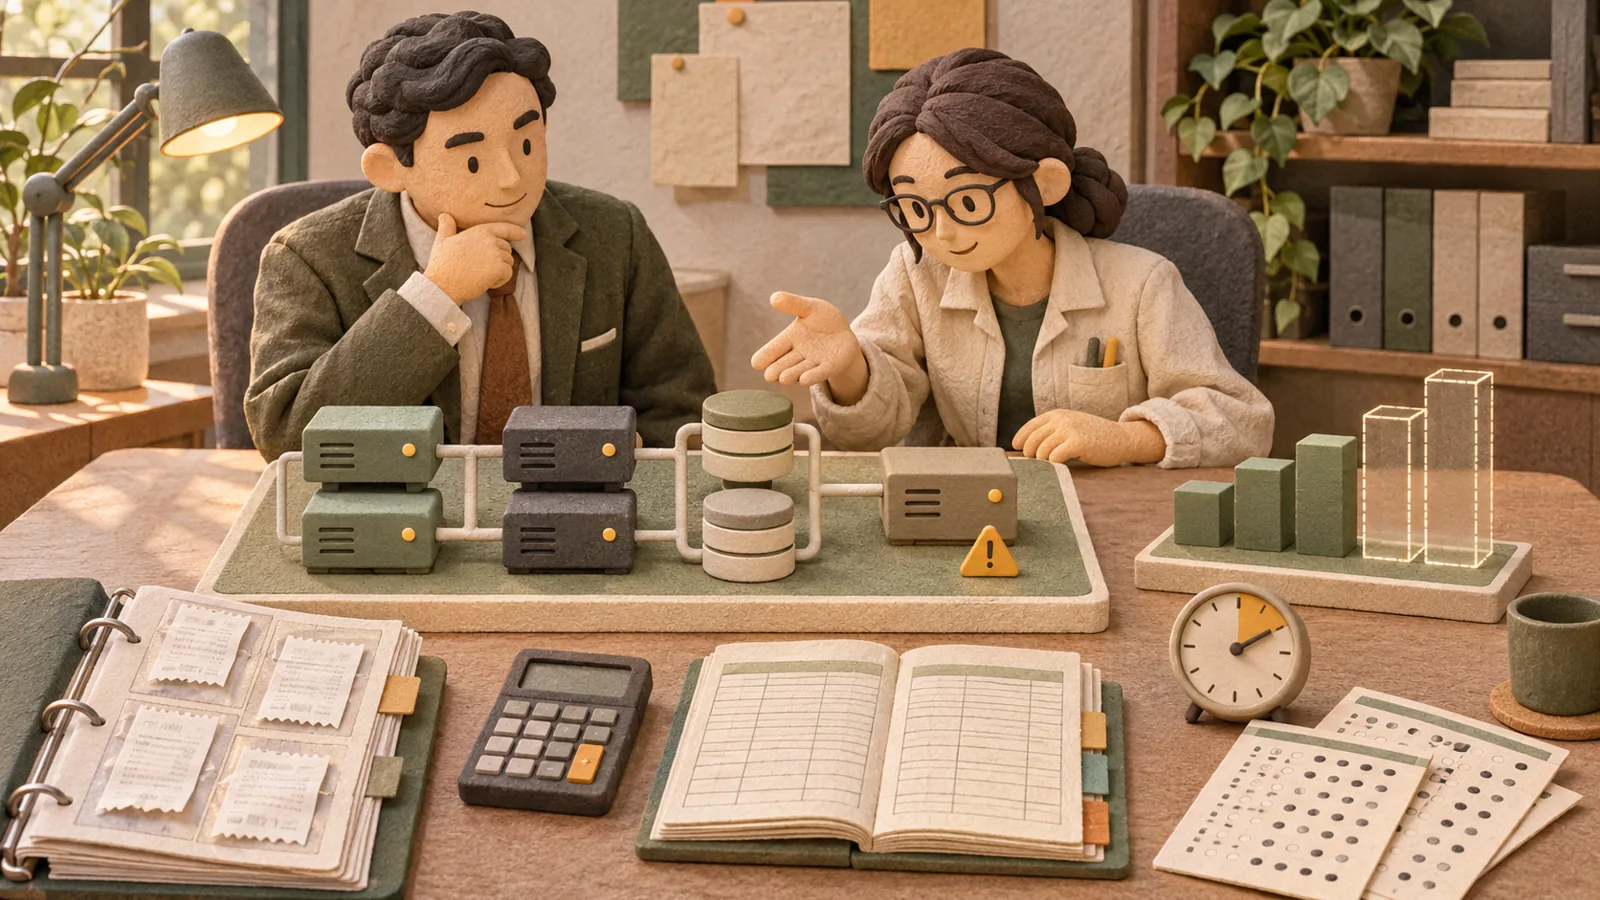
Database writes, pool connections, cache/lock contention, payment/courier quotas, network and background work may cap the whole system before these totals. Do not solve one saturation by flooding another tier. Use backpressure, bounded work and operation ownership; deferred jobs still need a freshness target and recovery budget.
NGINX least_conn selects using active connections and weights, not omniscient business cost. Least-outstanding-request algorithms are not identical to it. Long connections, multiplexing, request mix and upstream limits affect the choice. Compare policies with the real workload; round robin is not automatically wrong.
A preparation and acceptance map, not a throughput guarantee. Time-to-ready, surviving instances and shared limits must all pass the actual request mix.
Protect outcomes while controlling load
Retrying an upstream can repeat an effect whose first response was lost. NGINX retry rules constrain when another attempt can occur; method labels and proxy configuration do not replace application idempotency. Do not turn payment errors into indiscriminate POST retries. Keep durable operation identity, query unknown results and bound permitted retries with backoff/jitter, age/attempt limits and an owner.
Apply admission/rate controls where they preserve the business promise, with readable status and a safe way back. Avoid unbounded queues that make requests succeed after the customer was told they failed. Queue age should measure eligible ready work, not intentionally future scheduled items. Distinguish accepted/pending/completed orders, stock reservation, captured payment and delivered goods.
Scale in only when arrival load, active work, recovery backlog and minimum failure capacity permit it. Drain and supervise termination; wait for or safely recover owned work and preserve reconciliation evidence. A timer saying the event ended does not mean every payment and fulfilment obligation ended.
Rehearse the arrival pattern and release capacity with evidence
Define business success, error/timeout limits and latency objectives before the test. Include browse, search, variant selection, cart, login and authorised checkout fixtures in realistic proportions, plus cache misses and retries. Protect external effects so a rehearsal cannot charge real customers or dispatch parcels.
k6 distinguishes open and closed workload models. For a step-arrival question, make sure slow responses do not silently reduce the offered demand. An arrival-rate iteration can contain multiple requests; inspect actual sent/completed rates, dropped iterations and generator capacity, not just configured virtual users.
Exercise the target step, sustained peak, a justified higher scenario, cold/revalidation events, instance loss and safe scale-in. Capture tail latency, business outcomes, admitted/rejected work and per-tier waits. Abort using agreed limits and an operator/kill path; a CPU guard alone cannot detect wrong duplicate charges. Change one material constraint, then rerun the relevant scenario.
For the midnight example, a prepared team can show which instances are ready before traffic, what remains after failure and how overload is handled. Only an integrated test can say whether the 440-request mix meets its objective. Ask any supplier—including StoreConsole—to demonstrate that evidence in the actual version, enabled modules and deployment offered.
Reviewed 5 November 2026. Anichur Rahaman, creator of StoreConsole. Traffic, timing, memory and capacity numbers are planning illustrations, not tests performed or guaranteed product throughput.



 Software Architecture