Queues That Finish the Work: Capacity, Ownership and Safe Recovery
A fast response can hide unfinished business work. Size the worker pool for arrivals and backlog, preserve the accepted record and make retries accountable.
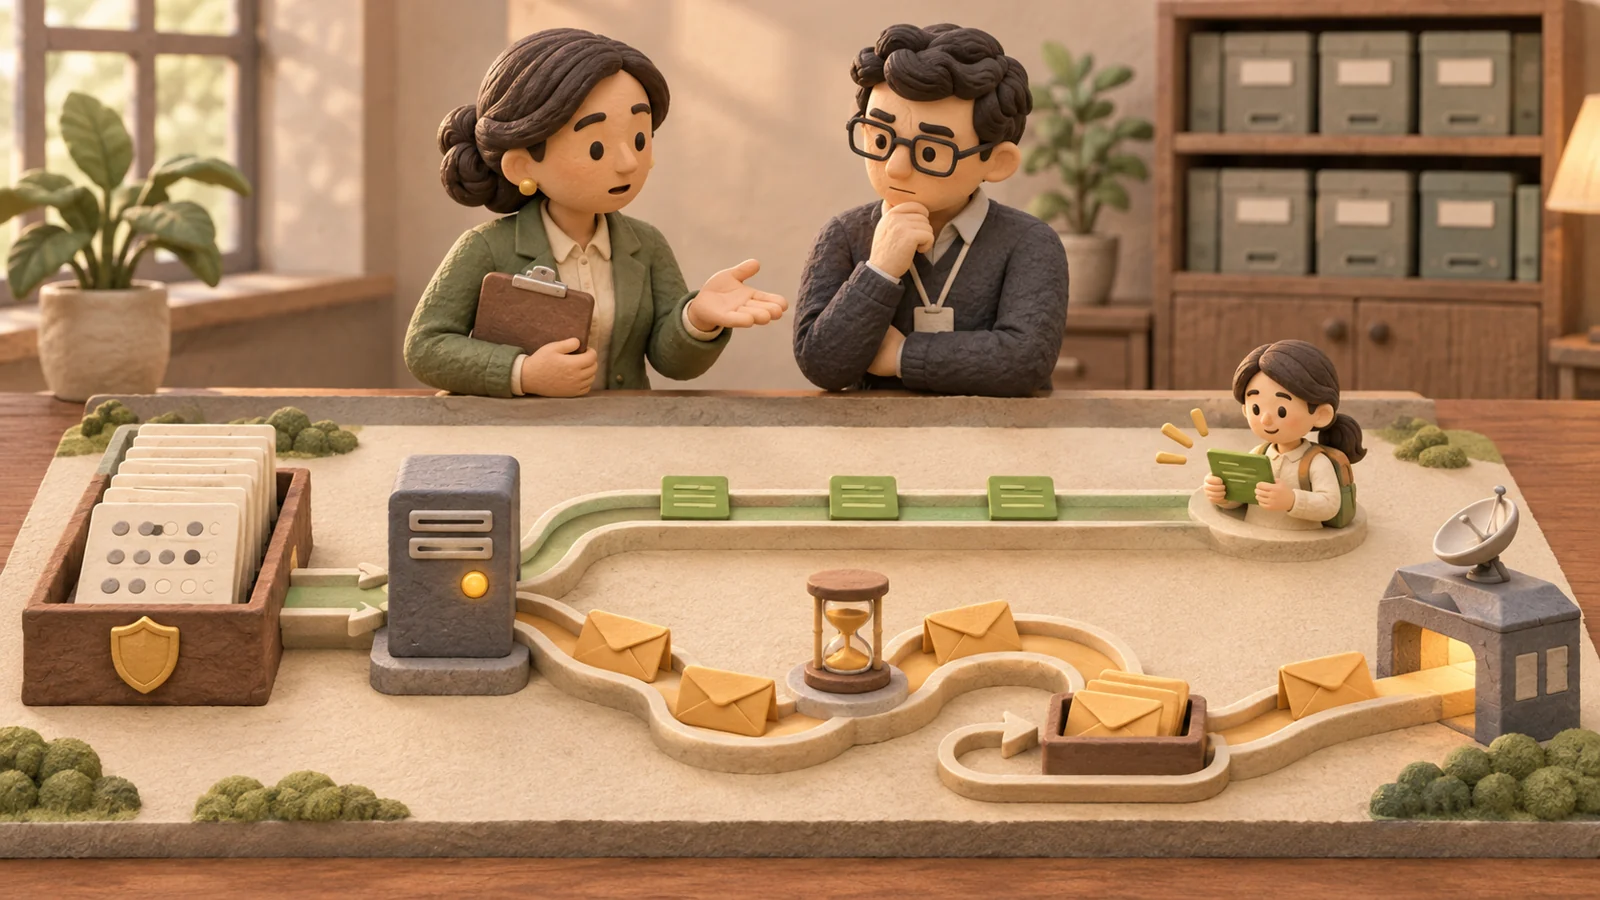
At 9:00 an exam platform has durably accepted 1,000 answers, but grading is still waiting. The student should see “received; grading pending”, not an invented result. This teaching scenario also fits an ERP’s invoice generation or an order’s shipping label: accepting a request and completing the background obligation are different events.
A queue absorbs uneven arrivals; it does not create processing capacity or prove the business action finished. This part 2 of Engineering for High Volume follows that obligation from its authoritative record through a bounded worker pool, an uncertain external result and a controlled recovery. No personal test or customer outcome is asserted.
Save the accepted fact before promising success
The validated submission must survive before the interface says it was received. Do not put the only copy of an answer, order or approval into an expendable queue. Record what was accepted, who authorised it and which work is still owed; later grading, notification and external delivery have separate states.
Laravel’s queue documentation describes dispatch after commit. That avoids work reading an uncommitted record or surviving a rolled-back transaction. When committing a business record and publishing to another queue are separate writes, a crash after commit can still leave no message.
For critical obligations, use an appropriate atomic queue/database design or a transactional outbox that stores publication intent with the owned change. A recoverable relay publishes it. Duplicates, retention and operational failure still need controls; “after commit” alone is not a no-loss guarantee.
Separate service classes, then reserve the resources they need
Set a completion/freshness objective for each kind of work. Submissions, payment reconciliation, notifications, image processing and reports may have different urgency, cost and failure behaviour. Separate queues help route them, but do not reserve CPU, memory, database capacity or provider quota by themselves.
Use explicit supervisor/pool budgets for work that needs independent capacity. One worker listing a high queue first still executes one job at a time and can starve later queues. Dedicated capacity is not pre-emption of a running long job, and low-priority work can still contend on the same database.
Separating worker and web compute can protect resource budgets. Containers/cgroups or separate nodes can both be appropriate. Shared database, cache and network failures can still affect both, so “move workers to a node and pages can never suffer” is not a credible promise.
Count arrivals as well as the backlog
Assume an instantaneous ready backlog B=1,000 jobs and mean worker-occupied time s=0.12 seconds/job, including relevant I/O waits. Existing work totals 120 worker-seconds. With no new arrivals, 12 perfectly balanced workers give a fluid lower bound of 10 seconds. Even identical indivisible jobs require 84 waves×0.12=10.08 seconds; dispatch, skew, retries and contention add more.
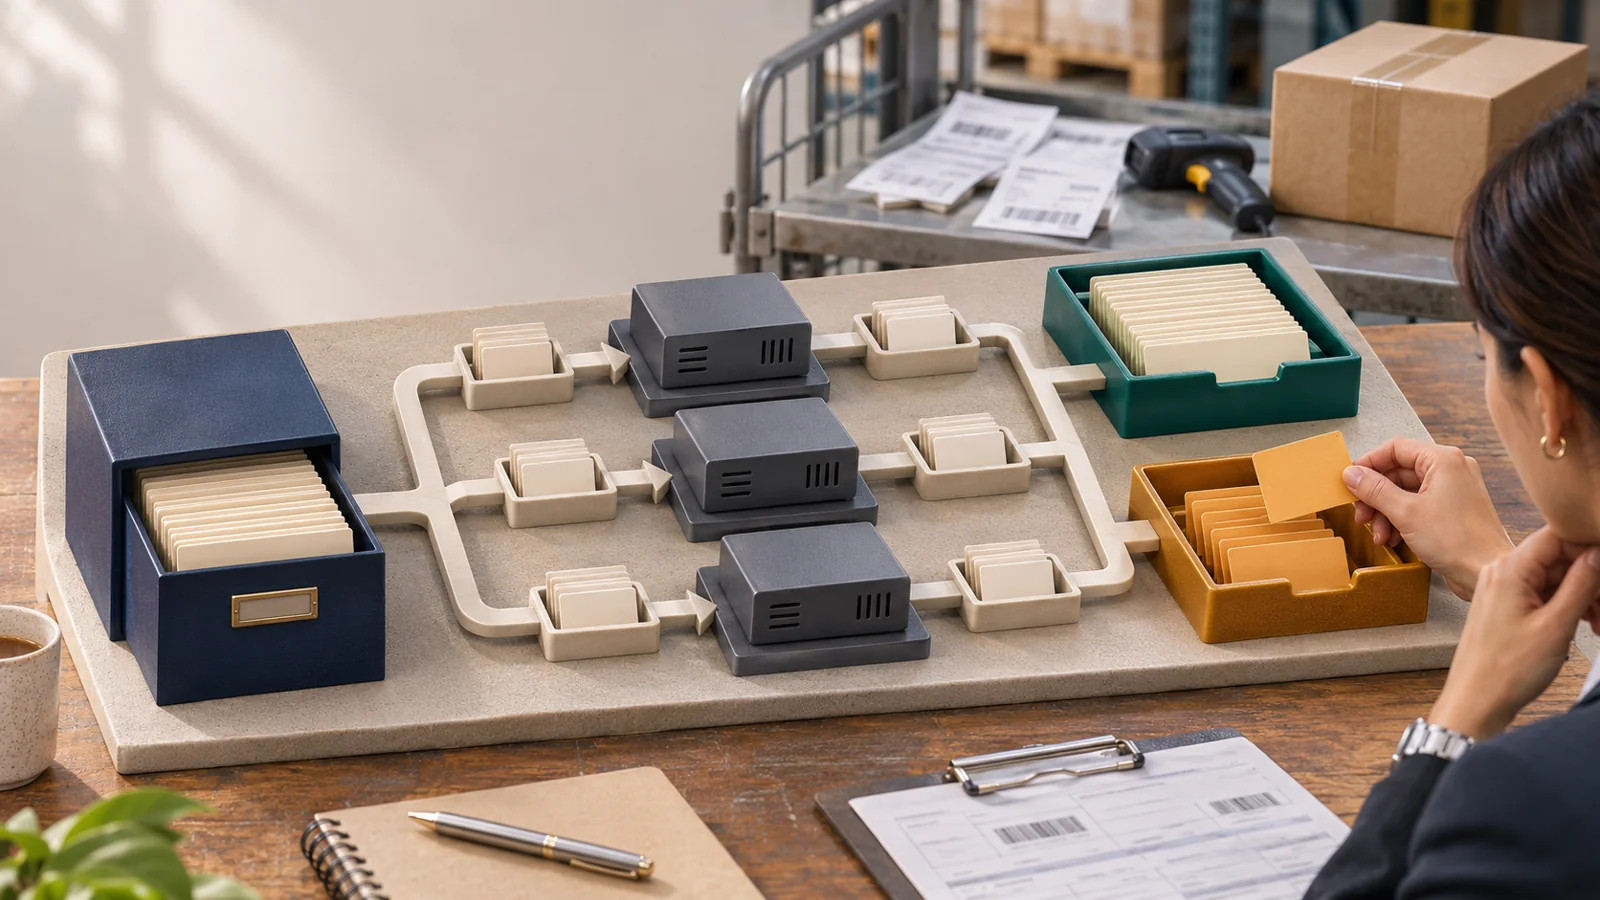
Now assume 50 new ready jobs/second continue to arrive. With w workers, ideal throughput is w÷0.12. Backlog drains only when that exceeds 50; ideal drain time is B÷(w÷s−50). The table is a planning model, not a measured benchmark or a deadline guarantee.
For a 10-second drain target under those arrivals, the fluid lower bound is w≥s×(50+B÷10)=18. Choose tested headroom for variability, failures and dependencies. Do not divide job count by runtime and call that a worker count: units and the target horizon matter.
Workers
Ideal throughput jobs/s
Net backlog drain jobs/s
Fluid drain of 1,000
6
50
0
No net drain
12
100
50
20 seconds
18
150
100
10 seconds
Adding workers eventually meets a shared bottleneck. Measure useful completions, oldest eligible-ready age, occupied time distribution, database waits, lock contention and provider limits. A short queue can coexist with many reserved/stuck jobs; delayed future work should not inflate a ready-work alert.
Scale processes or replicas for the deployment you actually run
Current Laravel 13 Horizon guidance distinguishes simple distribution of worker processes, auto allocation and ordered-queue false mode, which may still scale process count. Auto does not enforce strict queue priority from array order. Check the installed version instead of treating “false” as a universal fixed-pool switch.
Horizon supervises Redis queue workers; its current documentation excludes Redis Cluster. It can run on multiple compute nodes, but does not itself provision those nodes. Minima, maxima and resource caps must be summed across queues, supervisors and replicas. An auto limit on one supervisor is not automatically the whole deployment’s global limit.
KEDA 2.21 can supply event-driven scaling around Kubernetes workloads, with HPA controlling replica changes. Available compute, polling/metric freshness, activation, image startup, readiness and scale-down rules determine actual reaction. Neither pods nor local processes have a universal seconds/minutes guarantee, and neither is free of resource/operating cost.
Use a signal that matches the actual driver. A Redis list length may count ready entries but miss reserved/delayed work. Pre-provision a justified minimum for a known burst and keep reactive capacity within tested limits. Do not make a second scaling loop fight the first.
Timeout, reservation expiry and retry delay are different clocks
A hypothetical Horizon/Redis timing budget is external-call deadline 10 seconds, job timeout 45, supervisor timeout 60 and connection retry_after 90. These are illustrative, not shipped settings. Horizon’s timeout must exceed the job’s and remain safely below the queue retry_after boundary; test the actual driver, runtime extensions and termination behaviour.
retry_after is not the delay between application retries. It controls when a reserved job can become eligible again if it was not properly completed/released. If a worker still runs when another receives the same job, concurrency can duplicate effects. SQS visibility and other drivers have their own contracts.
Illustrative boundary
Seconds
Purpose
External call
10
Bound the actual call
Job timeout
45
Bound one job execution
Horizon supervisor timeout
60
Above job; below reservation expiry
Redis retry_after
90
Reservation eligibility, not retry backoff
Set attempt and total-age limits, explicit exception/release behaviour and backoff with jitter where appropriate. Invalid permissions or bad data need correction, not endless retries. A failed-job store needs an alert, owner and reviewed retry/cancel route; merely writing a failure row is not recovery. Some middleware releases consume attempts, so inspect actual attempt semantics.
Make a duplicate attempt safe at the effect boundary
Checking “already done” at the start can race with another worker or crash before its receipt is saved. For a local database effect, atomically claim the scoped unique operation, apply the mutation and store the processing result together. Queue uniqueness or an overlap lock does not by itself prove an external payment/email happened once.
For a provider call, retain a durable business reference and use supported idempotency/status lookup. Stripe’s idempotency contract illustrates why key scope, parameters and retention matter. If a response is unknown, query/reconcile the original operation before issuing another; a fresh key can create a fresh charge.
A paid invoice whose PDF generation failed needs document recovery, not another collection. An acknowledged email request is not proof of inbox delivery. Keep task attempt, provider result and business completion distinct, and make replay respect approved current state rather than clearing all dedupe keys.
The queue is transport for work owed. A retry must preserve the business operation and an unknown provider result must remain visible.
Budget memory, privacy and deployment recovery together
Budget resident worker/runtime overhead, retained memory, heavy-job peaks and shared/container base costs. For illustration, 10 workers with 128 MiB private/incremental allowance consume 1,280 MiB=1.25 GiB before other overhead/headroom. That does not prove a 2 GiB container is enough. For mixed pools, sum each pool’s own worker×memory budget and test peak coexistence.
Streaming/chunking can reduce memory, but libraries may still buffer and splitting jobs changes ordering/recovery. Measure before/after rather than claiming an invented 288→128 MiB saving. Recycle long-lived workers when appropriate; adding RAM or workers without evidence may leave the real bottleneck unchanged.
Pass minimum scoped data; an ID is not permanent permission to fetch a record. Recheck authority and business state in the owning service. Protect broker transport/storage, payloads, failed records, dashboards and exports. Encryption of a payload does not protect every metadata field or general log. OWASP’s logging guidance supports useful evidence without dumping secrets or salary/customer documents.
Deploy compatible code/schema/payloads and gracefully replace supervised long-running workers. You need not empty every queue. Allow current work to finish or recover safely within tested termination/visibility limits; preserve old-version compatibility until old work is handled. Starting the scheduler last alone cannot fix incompatible jobs or guarantee no duplicate schedule.
Run the queue as a set of visible obligations
Laravel’s scheduler guidance allows coordinated single-server work using shared atomic locks; one fixed cron node is not the only topology. Test expiry, overlap, failover and missed-run recovery, with business idempotency. A periodic relay can be valid; a long-lived process is not a universal cure for memory pressure.
Rehearse crash before/after commit, publish failure, concurrent duplicate, timeout with unknown result, bad payload, revoked access, heavy-job peak and deploy mid-job. Isolate real external charges/messages. Measure pending obligations and actual effects against the same scope/time/state, not just “queue depth zero”.
The useful 9:00 dashboard can say answers received, grading pending/completed, notifications accepted/confirmed and exceptions owned. The exact completion target still needs an integrated test. Ask a supplier—including StoreConsole—to demonstrate this path, permissions and bounded recovery in the offered version and enabled modules.
Reviewed 5 November 2026. Anichur Rahaman, creator of StoreConsole. Submission, capacity, timing and memory examples are illustrative; no customer benchmark or installed software guarantee is asserted.



 Software Architecture