The Result Was Fast. Its Queue Was Not — NovaCommerce 4
A 0.34-second result job waited behind slow AI work. Separate lanes helped, but durable submissions, bounded retries and worker recovery still mattered.
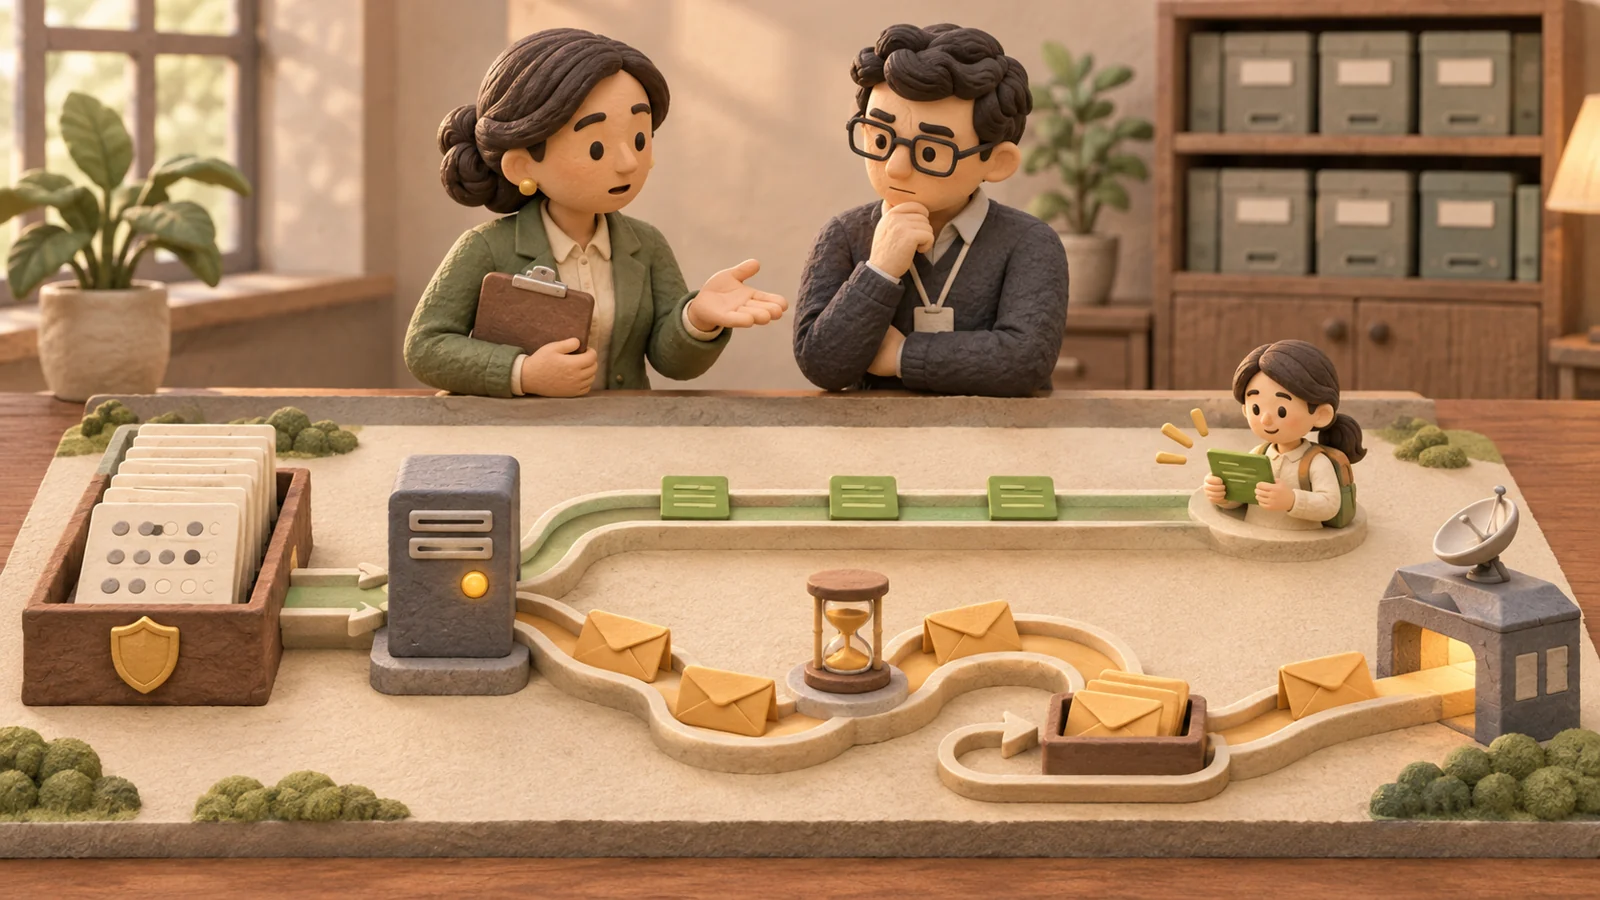
A student finishes an exam and waits for the merit card. The actual recomputation takes about 0.34 seconds. In the 6 October case record, some cards arrived 10–115 minutes late. The short job was waiting behind about 2,000 AI jobs taking roughly ten seconds each, with two workers sharing the lane.
NovaCommerce is an anonymised course-and-exam platform. Part 4 retains the existing September–October 2026 observations and separates implemented changes from recommended safeguards. It is not a new incident audit or a StoreConsole performance benchmark.
Shared state moved the failure boundary
Externalising sessions, cache and queues to managed Valkey helped replace web nodes. It also created a shared dependency: a 6 October load test recorded 2,854 connection timeouts. The case described fresh TLS connections and a resize from 4 GB to 8 GB per node, primary plus standby. A later 25–500 requests/s ramp reported zero application errors but 143 load-balancer errors at CPU saturation. The connection failure changed; the complete path still failed requests.
A timeout does not by itself establish memory exhaustion or prove a specific handshake CPU cost. Investigate connection churn, limits, network and server metrics. The recorded 12.5% memory use during an exam is one observation, not a capacity guarantee. noeviction prevents memory-pressure eviction but can reject new writes; it does not provide queue persistence, lossless failover or isolation between cache, sessions and jobs.
Give urgent outcomes their own serving capacity
The team separated the AI narrative lane from merit/position work. The case reports merit cards then arriving in roughly a minute. Separate names alone would not guarantee this: process allocation, database connections and shared CPU must also leave room for urgent jobs.
The old arithmetic explains the backlog: 2,000×10=20,000 worker-seconds; divided across two workers, about 10,000 seconds, or 166.7 minutes, before overhead. This illustrates possible waiting, not an exact completion prediction. It is independent of the later provider limiter. At a shared limit of eight calls/minute, 2,000 one-call jobs need at least 250 minutes—4 hours 10 minutes—without retries or new arrivals.
Failure class
Response
Completion evidence
Transient throttle
Shared limit; Retry-After; bounded jitter
Original operation reconciled
Provider credit/auth problem
Pause; alert; repair cause
Controlled resume, deadline checked
Unknown external outcome
Query/reconcile before replay
No duplicate side effect
Retry deadline reached
Retain failed/pending record; review
Audited replay or explicit final state
Worker lost
Restore processing and reconcile ledger
Accepted work accounted for
Retry a classified problem, not every refusal
The historical lane used a shared eight-calls/minute limiter, 1–15-minute exponential backoff with jitter, a retry window of up to 12 hours and temporary template text. The case also recorded roughly 3,800 delayed narratives during a credit shortage, with processing resuming after credit was added. That is a recovery observation, not proof that every delayed job completed or none could expire.
Treat the configured rate as a case setting, not guaranteed provider entitlement: token and concurrency limits may also apply. Honour Retry-After where supplied. Retry transient throttling and temporary failures within an absolute deadline; stop or pause permanent authentication, invalid-payload and exhausted-credit failures and alert an owner. Show pending/template status honestly. At deadline, retain a reviewable failure and controlled replay path rather than silently losing work.
A network timeout may hide a completed provider call. Use stable operation identity, provider-supported idempotency or status reconciliation before a duplicate side effect. Refund an internal allowance only for a confirmed unconsumed reservation; changing an app counter cannot refund a provider invoice. Keep billing reservations and completion records auditable. These are required design checks, not newly verified implementation in this historical system.
Urgent results and optional narratives have different service needs. This map includes recommended checks as well as historical case settings.
A single worker is a recoverable gap, not exactly-once
One fixed 4 vCPU/8 GB worker carried queues, scheduling, WebSockets and SMS; the gateway allowed one outbound IP. Its snapshot existed, while reserved-IP recovery, a standby worker and exam burst capacity were planned. A reserved address must actually support the required outbound egress and provider allowlist; assigning it alone does not prove SMS works.
If that worker fails, background completion stops. Accepted answers must already have a durable authoritative record; do not promise their safety solely because a queue lives in Valkey. Test persistence, acknowledged work reconciliation and replay after failover. Multiple workers are normal when safe reservations and idempotent effects exist. One scheduler or a distributed lock alone cannot guarantee exactly-once business effects after crashes. Set job timeout below reservation visibility/retry_after where applicable, and distinguish that interval from backoff.
Fix identities and retain evidence
Two limiter layers had counted IP instead of an authenticated student. On 7 October, 74% of calls to one dashboard endpoint reportedly returned 429; account-and-route keys addressed that endpoint afterwards. This does not mean every abuse limit should be removed. Keep per-account, guest/network and provider protections, and trust forwarded headers only through controlled proxies. A signed IP still is not authorisation.
Backend logs were shipped through Fluent Bit to OpenSearch. Frontend log shipping remained planned, with about 440 MB/day locally at risk on deletion. Shipping logs needs bounded buffering, delivery monitoring, restricted access and redaction of answers, tokens and private data; off-node does not mean instant lossless delivery.
The exam digest watched starts/submissions, per-node requests and 5xx, CPU, queue health and failed jobs. Lowering a pool minimum during the exam reportedly caused about 360 request failures in two minutes. The “do not scale in during exams” runbook reduced risk but was not an enforced lock. Watch oldest-job age and pending outcomes, not only CPU or a zero failed-job count. Part 5 asks what the tests actually proved.
Reviewed 6 November 2026. Anichur Rahaman, StoreConsole founder. Existing case observations retained; primary sources explain general behaviour, not a fresh verification of the private system.



 Software Architecture

