An exam starts at a fixed time. Students arrive together, and the platform has to accept their work while the clock keeps running. Buying a larger server does not answer the important questions: what happens when a node fails, a shared service slows down, or a deployment interrupts an active request?
In this five-part case study, we follow an online course and exam platform from its original setup through the changes made for a scheduled peak. Part 1 shows how we identified the risks before choosing the infrastructure.
About the case: NovaCommerce is an anonymised name. The configuration and measurements below come from the September–October 2026 project records. They describe that platform and workload, not a Store Console benchmark. General technical guidance was reviewed on 3 November 2026.
Start with the business event
An ordinary day's average traffic was a poor guide to exam capacity. The demanding event was the opening minute: students loading questions, checking their session and beginning the exam at roughly the same time.
We translated that event into four requirements:
Be ready before the start. Capacity must already be healthy when students arrive.
Protect acknowledged submissions. Define when an answer is durably saved and how a retry avoids creating duplicates.
Keep changes from interrupting active work. Deployments and node removal need health checks and request draining.
Make the cost explainable. Each recurring resource should address a measured capacity need or a defined failure.
These were requirements, not claims that every failure scenario had already been tested.
The original architecture and its weak points
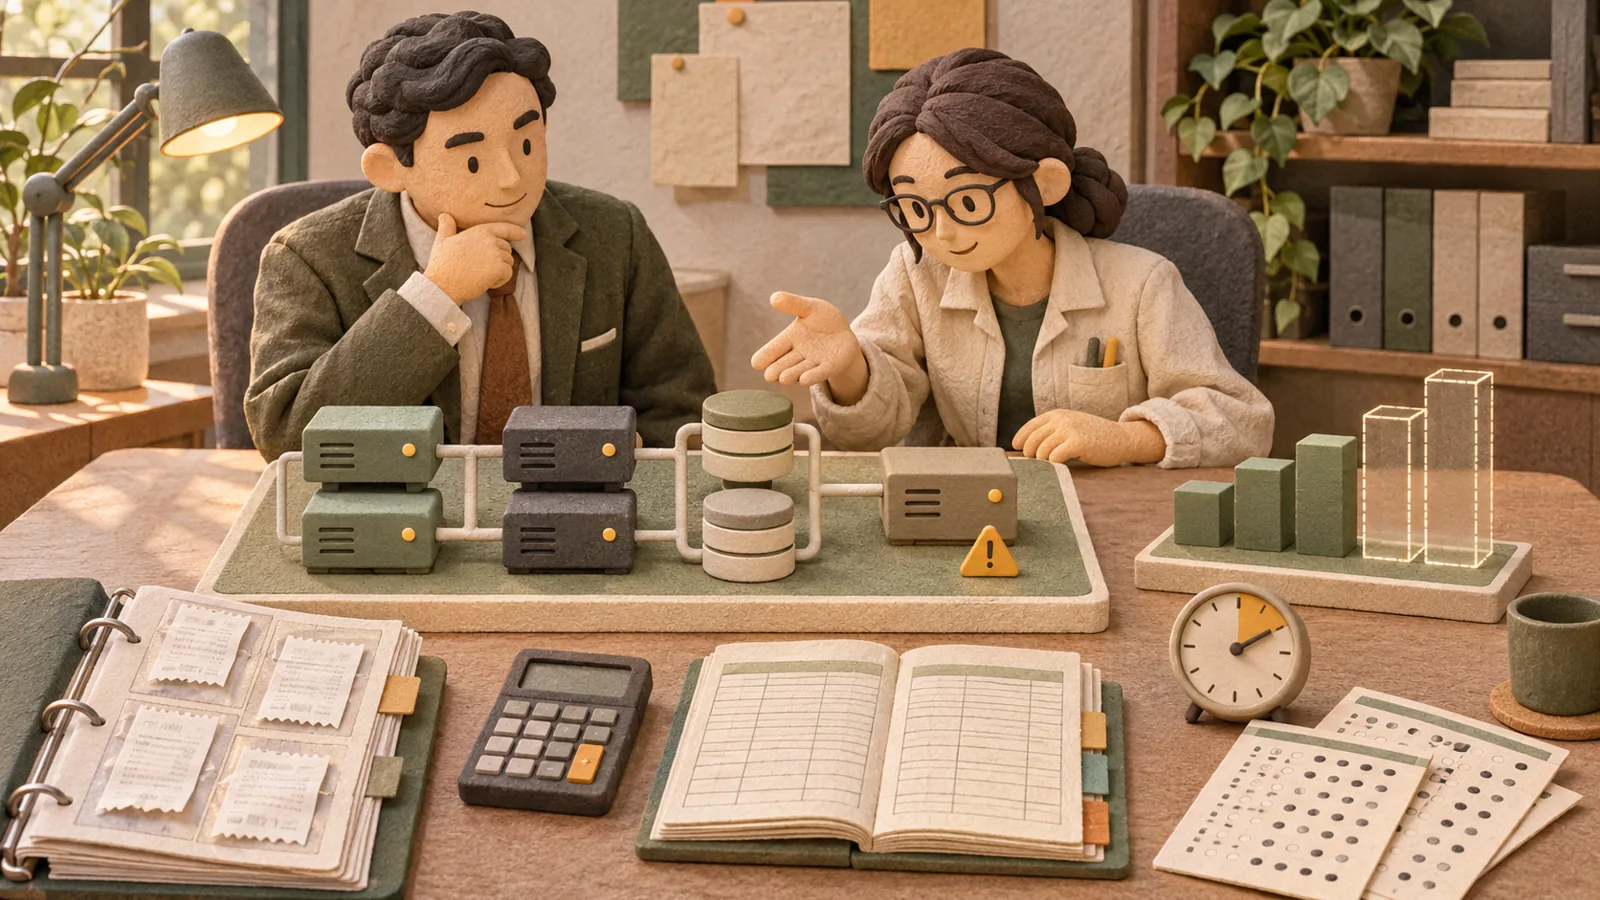
The original failure points and the acceptance evidence required before an exam. This is a teaching map of the historical case, not a measured availability guarantee.
The frontend ran one Next.js container on an 8 vCPU, 16 GB Droplet, with no load balancer in front. Its loss could make the public site unavailable. The backend was better separated: two 4 vCPU, 8 GB nodes served Laravel through nginx and PHP-FPM, while background jobs, the scheduler and WebSockets ran on a separate worker.
The backend load balancer targeted fixed Droplet IDs. Adding another server therefore required registration; the configuration did not automatically discover new capacity. Sessions, cache and queues were already externalised in managed Valkey, which made replacing web nodes easier.
MySQL had one 8 vCPU, 32 GB managed node and no configured standby. A managed service can replace a failed node, but that is different from having a replicated standby ready for promotion. The single worker was another failure point for asynchronous work.
Two additional Droplets were powered off as recovery capacity. They could support a recovery procedure, but they were not serving traffic and could not provide automatic failover.
A useful distinction: a single JavaScript event loop can limit CPU-heavy rendering, but Node.js also uses a worker pool and native operations. One container alone does not prove that seven of eight cores were idle. The right process count comes from profiling and load testing.
Define availability as a test you can run
Instead of labelling the whole platform “highly available”, we asked what a person should experience during a specific failure.
Database failure: a documented failover path restores service, and the application handles transient disconnections.
Deployment: a replacement becomes ready before the old node stops accepting traffic; active requests get time to finish.
Scheduled peak: sufficient capacity is healthy before the event, with spare headroom for uneven traffic.
Availability and data durability need separate evidence. Stateless web nodes make replacement possible; they do not by themselves guarantee that an answer survives. That also depends on database commits, replication and persistence settings, retry handling, backups and recovery tests. A single-region design also does not establish recovery from a regional outage.
Three findings, three different responses
1. HTTP 429: the limiter counted the wrong identity
On 25 September, students sharing a school or carrier network were receiving “too many requests”. The API limiter used their IP address because the expected authenticated identity was not being resolved. Many people therefore shared one allowance.
The correction keyed authenticated limits to the student or instructor account, retaining an IP-based fallback for guests. Extra servers would not have changed that rule. Identity-based limits still need separate abuse protection; they are not a reason to remove throttling.
2. Valkey connection timeouts: a shared dependency failed under load
The 6 October test recorded 2,854 application errors with Valkey connection timeouts. The case records describe fresh TLS connections adding overhead and a resize from a 4 GB primary-and-standby configuration to 8 GB per node.
After the resize, a gradual 25–500 requests/second ramp reported zero application errors, but 143 load-balancer errors while backend CPU saturated. That is evidence that the application-timeout failure was removed in that run. It is not a clean end-to-end pass at the highest load: requests still failed.
A timeout alone does not establish a memory shortage. For another system, investigate connection churn, limits, network behaviour and service metrics before assuming that a larger plan is the answer.
3. Backend CPU: capacity became the next constraint
For the tested API mix, a 4 vCPU backend node reached roughly 65–70 requests/second at full CPU. That is an observed saturation point, not a safe operating target or a portable benchmark. Reducing CPU work and adding capacity are both options to evaluate.
In one test, the first extra autoscaled node arrived about seven minutes after CPU reached 99%. That delay was specific to this setup. For a scheduled exam, the practical response was to pre-scale and verify readiness before the start.
Keep the cost comparison honest
The original case budget put the web tier at approximately $416/month, including $112/month for the powered-off Droplets. Those are historical September–October 2026 figures; they exclude the databases, Valkey and storage. They should not be compared with a later full-stack bill.
DigitalOcean still bills reserved CPU Droplets while they are powered off. Whether cold capacity is worthwhile depends on the recovery time it actually provides. Ask what failure a resource covers, how quickly it can help, and when that procedure was last tested.
Provider plans also change. DigitalOcean's current documentation announces restrictions on PostgreSQL and MySQL Standard Edition plans beginning 15 October 2026 for accounts that have never created a PostgreSQL or MySQL cluster and 30 November 2026 for all accounts. Check current plan eligibility and prices before reproducing a historical configuration.
Use the same review before your next peak
For an exam, product launch or checkout surge, write down the critical request path. Identify each shared dependency and ask what happens when it becomes unavailable. Then test the expected workload and measure successful responses, tail latency and failures across the entire path.
Change the layer the evidence identifies, then repeat the test. The goal is a service that handles the business event within a defined failure and recovery budget.
Case configuration, incident counts and test observations are historical project records. The sources below support the general explanations, not those private measurements.
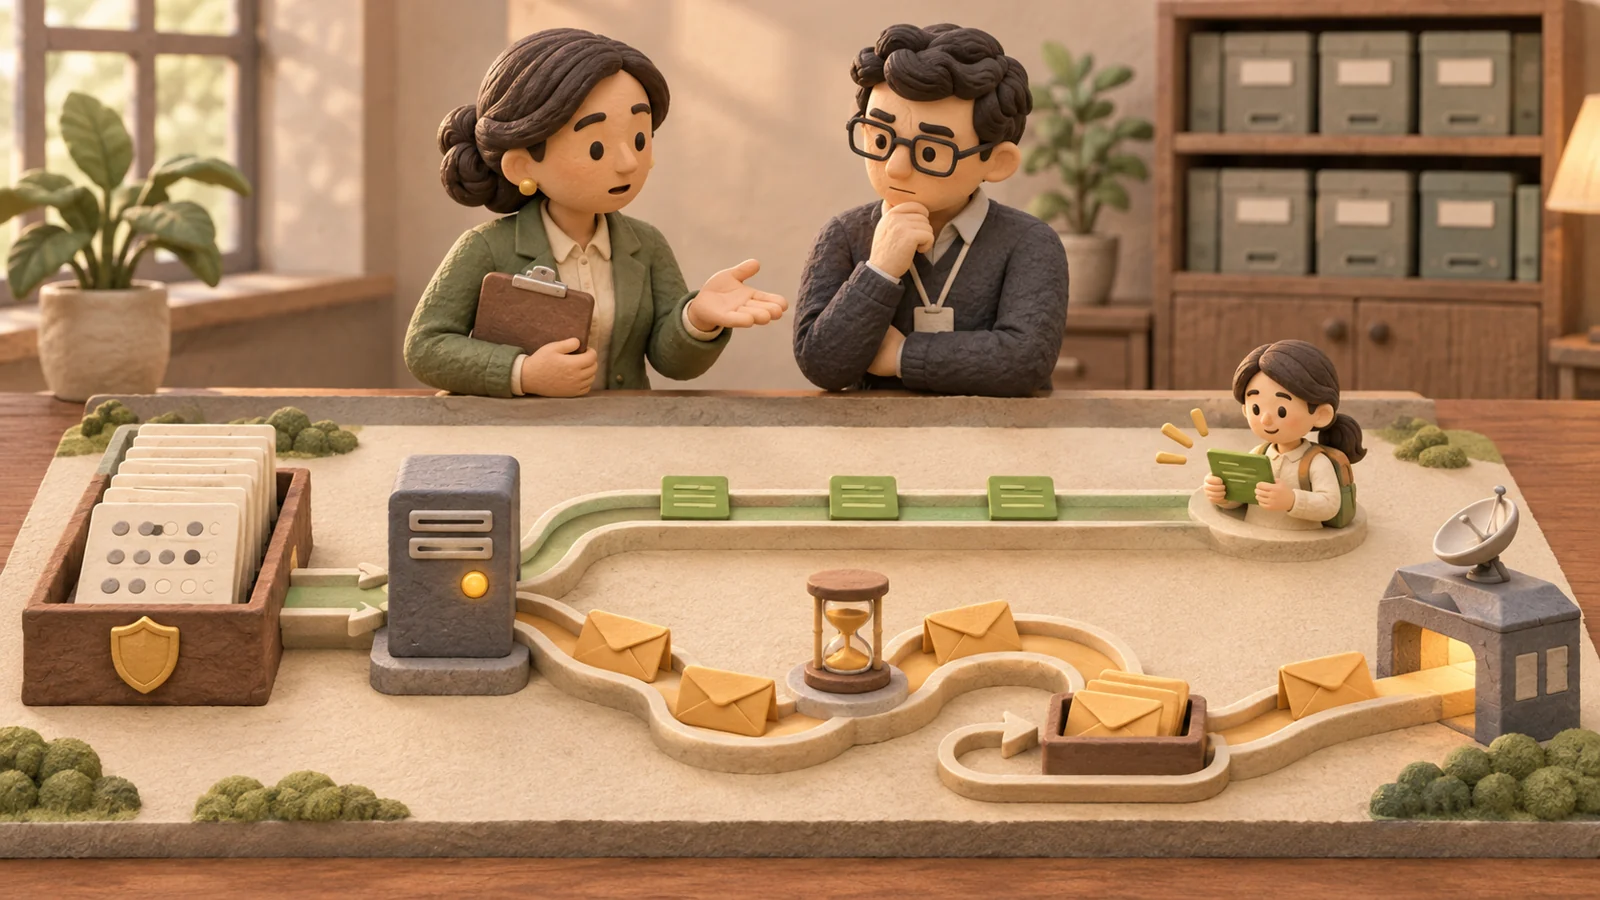
Reviewed 6 November 2026. An accepted answer needs an explicit durable-save receipt, an operation identifier and an idempotent retry path. A queued job is not the only copy of the answer. A standby, a backup and a successful restore test solve different problems; none alone proves zero data loss. The historical incident counts below have been preserved from the existing case record, not independently re-measured in this editorial review.