Checkout আটকে, CPU শান্ত: বাকি কাজের খোঁজ দেয় যে Observability
সবুজ server graph-এর পেছনে order আটকে থাকতে পারে। Business outcome-কে metric, সুরক্ষিত log ও trace-এর সঙ্গে যুক্ত করুন; alert-এর action ও owner নির্দিষ্ট রাখুন।
সকাল 10:01-এ support জানাল, “Checkout আটকে আছে।” CPU মাত্র 40%, homepage-ও খুলছে। শেখানোর এই দৃশ্যে server সবুজ কি না আসল প্রশ্ন নয়। Customer সঠিক outcome পাচ্ছেন কি না এবং বাকি কাজ কোথায় অপেক্ষা করছে, সেটিই দেখতে হবে।
Engineering for High Volume-এর part 4-এ ছোট evidence chain গড়ব: business outcome, aggregate signal, নির্দিষ্ট operation ও controlled response । কোনো বাস্তব incident, ব্যক্তিগত benchmark বা guaranteed diagnosis time দাবি করা হয়নি।
মাপার আগে success-এর অর্থ ঠিক করুন
HTTP 200, completed queue job বা payment page খোলা paid order-এর প্রমাণ নয়। Eligible operation, correct result, সময়সীমা ও exclusion নির্ধারণ করুন। একটি proposed checkout SLI-তে 2 second-এর মধ্যে accurate result বা durable pending receipt লাগতে পারে। Payment/fulfilment completion-এর আলাদা freshness objective চাই; নইলে pending চিরকাল সবুজ থাকবে।
নিচের অঙ্কে 30 days-এ 99% good-event objective এবং 3,000,000 eligible attempt-এর planning envelope ধরা হয়েছে। Incorrect, failed বা too-slow outcome মিলিয়ে bad; একই attempt fail ও slow দুটো হলেও একবার গুনুন। এটি teaching assumption, measured StoreConsole SLO নয়।
Teaching calculation
Result
Planned eligible attempt /30 days
3,000,000
Allowed bad fraction: 1−99%
1%
Planned bad-event budget
30,000
Burst: 440×600
264,000
Bad event: 264,000×2%
5,280
Planned budget used: 5,280÷30,000
17.6%
440 eligible attempt/s-এ 10 minute-এ 264,000 attempt । 2% bad হলে 5,280 event planned 30,000 budget-এর 17.6% নেয়। Bad-rate ratio allowed 1%-এর 2×; কত সময়ে budget শেষ হবে বলতে traffic assumption চাই। Google SLO alerting guidance multi-window ও impact-aware alert-এর ভিত্তি দেয়। Fixed 2% universal paging threshold নয়; volume, risk ও urgency গুরুত্বপূর্ণ।
Signal যুক্ত করুন, identity গুলিয়ে নয়
OpenTelemetry signal aggregate metric, event log ও span-based trace যুক্ত করে। চার golden signal—latency, traffic, error ও saturation—এর সঙ্গে real business completion দেখুন। CPU ছাড়াও pool/lock wait, eligible-ready queue age, oldest unresolved obligation, storage ও memory দেখুন। ভবিষ্যতের জন্য scheduled job এখনই late নয়।
Evidence
প্রশ্ন
সীমা
Outcome counter
সঠিক result সময়ে এসেছে?
Eligibility ও প্রতি attempt একবার গণনা
Structured log
এই operation/attempt-এ কী হয়েছে?
Scoped access; sensitive field ন্যূনতম
Trace
Instrumented time কোথায় গেছে?
Coverage, overlap ও sampling limit
Audit/reconciliation record
বাস্তবে কী durable effect আছে?
আলাদা authority, retention ও recovery control
Request ID এক request-এর, trace ID instrumented work জোড়ে। Business operation ID relevant retry-তে থাকে, প্রতিটি attempt আলাদা চেনা যায়। Queue কাজ পরে linked trace-এ চলতে পারে। W 3 C Trace Context propagation rule দেয়, authentication নয়। Untrusted incoming ID validate/limit করুন, প্রয়োজনমতো safe internal correlation বানান; partner-এ নির্বিচারে sensitive context পাঠাবেন না।
Span instrumented time-এর evidence; automatic root cause নয়। Nested/parallel span overlap করে, তাই সব duration যোগে double-count হয়। Timestamp ও unit normalize করুন, নির্ভরযোগ্য duration মাপুন, deploy/config change mark করুন। কাছাকাছি release hypothesis, safe rollback-এর প্রমাণ নয়।
Latency distribution, success/failure population, count ও rate দেখুন। Mean capacity planning-এ কাজে লাগে, কিন্তু tail লুকায়। Prometheus histogram guidance aggregation বোঝায়: per-node p95 average করে fleet p95 বানাবেন না। Known window-এ compatible distribution/bucket বা সঠিক অন্য পদ্ধতি নিন।
প্রমাণ সংগ্রহ নিজেই incident যেন না বানায়
Structured log-এ timestamp, service/environment/release, normalized route, outcome/reason, duration/unit ও প্রয়োজনীয় scoped correlation থাকুক। Query string ছাড়াও raw path-এ personal data থাকে। Internal ID-ও sensitive হতে পারে; কমান ও access সীমিত করুন। OWASP logging guidance secret বাদ দেওয়া, access, integrity, retention ও log-injection control বোঝায়। Card data, password, token বা customer document telemetry-তে নয়।
প্রয়োজনীয় request/order/user ID protected searchable context-এ রাখুন, unbounded metric dimension-এ নয়। Prometheus label guidance high-cardinality series সম্পর্কে সতর্ক করে; Loki label guidance-এ stream label ও detailed searchable field আলাদা। প্রতি label-এ customer ID মাঝারি traffic-এও ছোট backend নিঃশেষ করতে পারে।
Purpose ও applicable requirement অনুযায়ী retention, deletion ও legal hold ঠিক করুন। Measured volume দিয়ে ingestion, index, query ও recovery size করুন; universal 2 GB logging node বা 30 day retention নেই। Collector drop, exporter failure, buffer, disk ও alert delivery দেখুন। Retry/backoff ও buffering সীমিত রাখুন, যাতে telemetry fail checkout না আটকে দেয়। Required durable audit evidence-এর নিজস্ব policy চাই; চুপচাপ sample/drop নয়।
OpenTelemetry sampling guidance-এ early head decision ও later tail decision আলাদা। Head sampling পরে হওয়া সব error trace রাখার guarantee দেয় না। Tail policy error/slow trace বেশি রাখতে পারে, তবে capacity, wait window ও consistent routing লাগে; upstream-এ বাদ পড়া span ফেরাতে পারে না। Loss/coverage record করুন, SLI-এর উপযুক্ত unsampled outcome counter রাখুন। Actual SDK/instrumentation version যাচাই করুন; সব integration stable ধরে নয়।
Alert থেকে সীমিত, যাচাইযোগ্য সিদ্ধান্তে যান
প্রথম screen-এ critical journey-এর good/bad volume ও latency, তারপর waiting work ও resource limit থাকুক, scope অনুযায়ী drill-down-সহ। Incident-এর device-এ পড়া সহজ চাই। External/synthetic check ও provider evidence internal metric-এর পরিপূরক; telemetry missing মানে zero error নয়।
Page-এ owner, affected scope, evidence, runbook ও escalation চাই। উপযুক্ত short/long window, অর্থপূর্ণ হলে minimum traffic এবং severity মিলিয়ে দেখুন। Security, data corruption বা আসন্ন capacity failure-এ user-error rate বাড়ার আগেই জরুরি action লাগতে পারে। কম volume-এর money mismatch noisy CPU-এর চেয়ে জরুরি হতে পারে।
Affected service ও business state যাচাই করে evidence রাখুন, reversible mitigation নিন। গত 15 minute-এর প্রতিটি release automatically rollback বা database restart নয়। Schema/API compatibility, in-progress payment ও accepted work দেখুন। External result unknown হলে আবার financial action-এর আগে original reference query করুন। Mitigation-এর পরে real outcome ও recovery backlog reconcile করুন; error chart কমাই closure নয়।
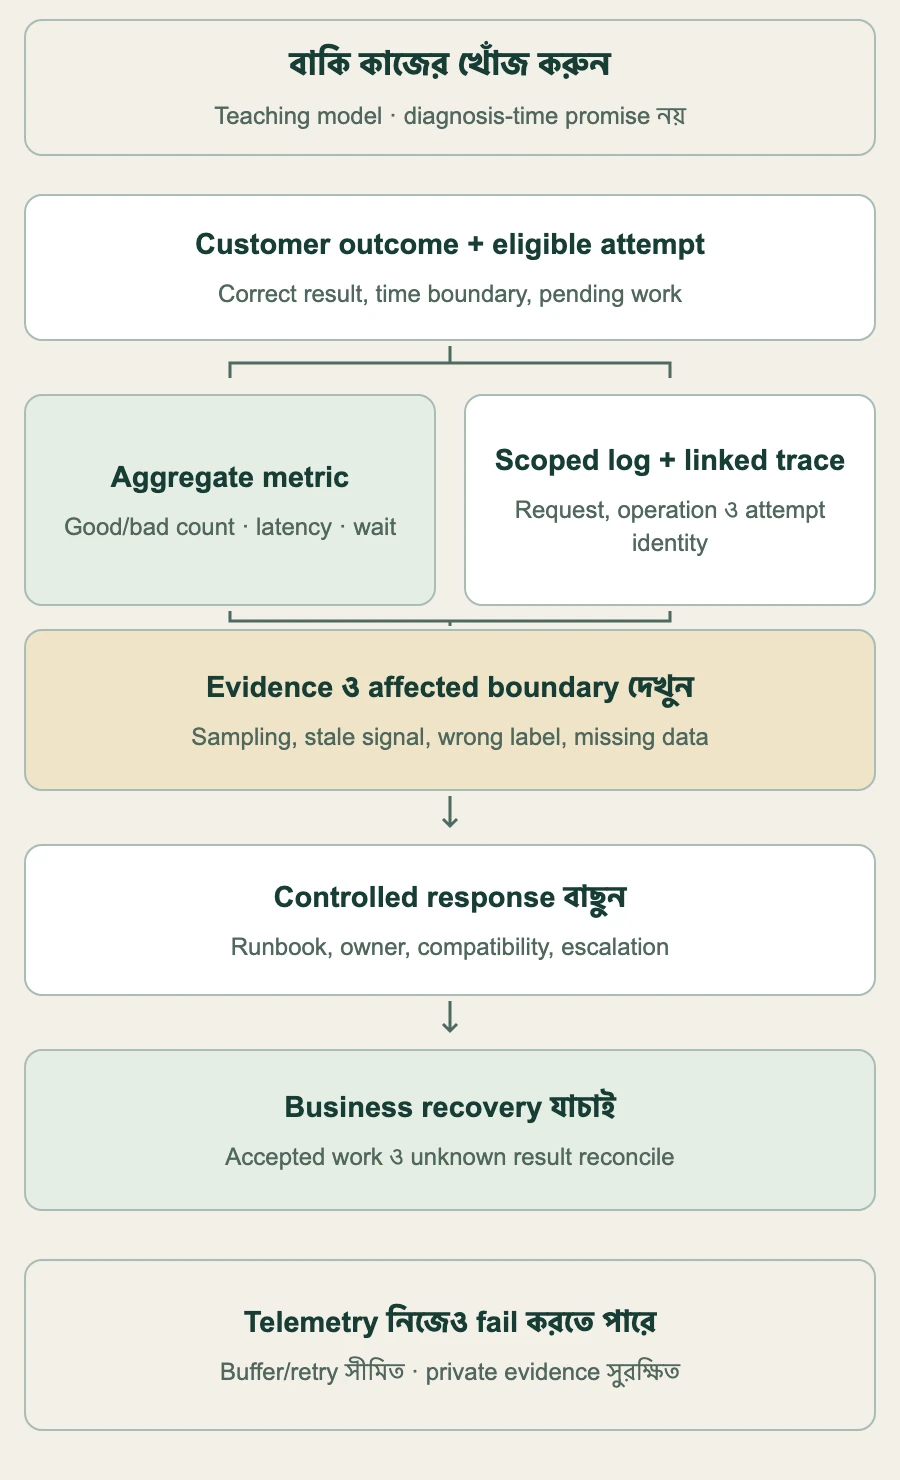
Teaching investigation flow । Correlation hypothesis ছোট করে; durable business record ও current permission নিরাপদ action নির্ধারণ করে।
Investigation ও monitoring failure দুটোই rehearse করুন
Isolated বা explicitly controlled load test-এ representative mix, cold cache ও dependency behaviour নিন। Offered/completed work, generator limit, test scope ও stop condition লিখুন। CPU guard test কখনো outage করবে না guarantee দেয় না। Provider/app chart window, denominator, unit বা scope-এ আলাদা হতে পারে; একটিকে ভুল বলার আগে সংজ্ঞা মেলান।
Slow dependency, failed enqueue, delayed callback ও exporter outage inject করুন। Alert owner-এর কাছে পৌঁছায় এবং linked record অন্য entity-এর data না দেখিয়ে unfinished work ব্যাখ্যা করে কি না test করুন। Result, decision ও limitation change-এর সঙ্গে রাখুন। সকাল 10:01-এ evidence অপেক্ষার জায়গা কমাবে ও recovery রক্ষা করবে; শান্ত CPU দেখে customer ঠিক আছেন এমন promise দেবে না।


 সফটওয়্যার আর্কিটেকচার

