सुबह 9 बजे exam platform ने 1,000 answers स्थायी रूप से स्वीकार किए हैं, grading बाकी है। Student को “received; grading pending” दिखना चाहिए, बनाया हुआ result नहीं। यही ERP invoice generation या order shipping label पर लागू है: request स्वीकारना और background obligation पूरी करना अलग घटनाएँ हैं। यह teaching scenario है।
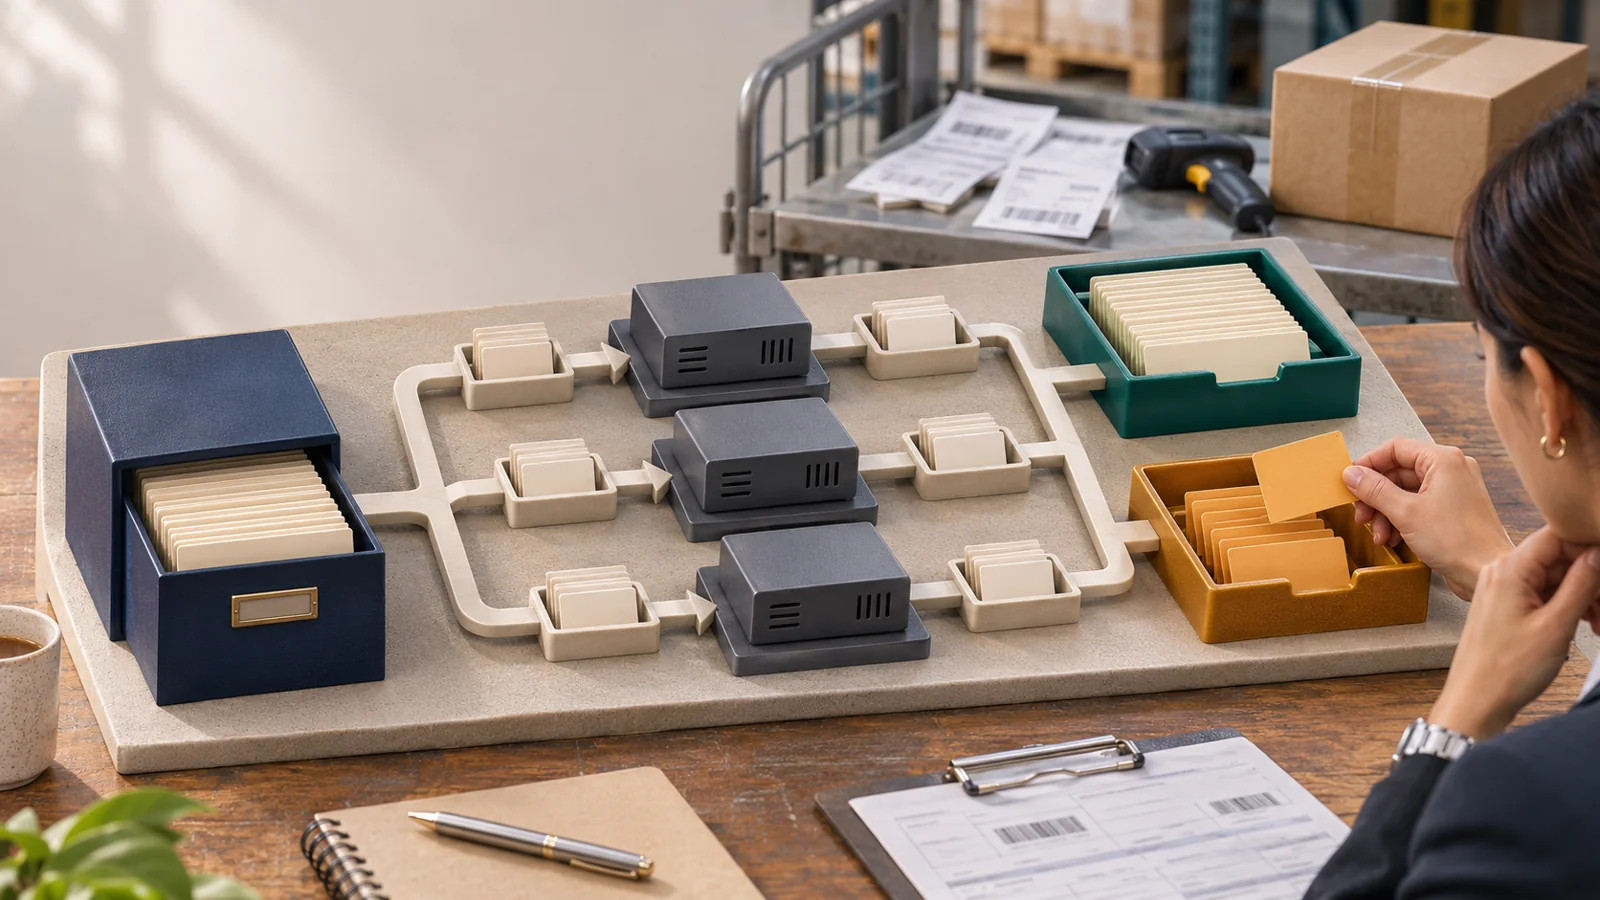
Queue असमान arrivals सँभालती है; processing capacity नहीं बनाती और business action पूरा नहीं सिद्ध करती। Engineering for High Volume का part 2 authoritative record से bounded pool, अनिश्चित external result और controlled recovery तक ज़िम्मेदारी का रास्ता है। व्यक्तिगत test या customer outcome का दावा नहीं।
Success बताने से पहले accepted fact बचाएँ
Interface received कहने से पहले validated submission बची रहनी चाहिए। Answer, order या approval की एकमात्र copy expendable queue में न रखें। क्या स्वीकार हुआ, किसने authorise किया और क्या बाकी है दर्ज करें; grading, notification और external delivery अलग states हैं।
Laravel queue documentation after-commit dispatch बताती है। इससे uncommitted record पर काम और rollback के बाद बचा job टलता है। पर business commit और अलग queue publication दो writes हों तो commit के बाद crash message छोड़ सकता है।
Critical obligation में उपयुक्त atomic queue/database design या owned change के साथ publication intent रखने वाला transactional outbox लें। Recoverable relay publish करे। Duplicate, retention और operational failure के controls फिर भी चाहिए; after commit अकेला no-loss guarantee नहीं।
Service classes अलग करें, फिर resources आरक्षित करें
हर काम का completion/freshness objective दें। Submissions, payment reconciliation, notifications, images और reports की urgency, cost और failures अलग हो सकती हैं। Separate queues routing देती हैं, अपने आप CPU, memory, DB capacity या provider quota reserve नहीं करतीं।
स्वतंत्र capacity के लिए supervisor/pool budgets दें। एक worker पर high queue पहले लिखने से वह एक बार में एक job ही करता है और बाद की queue भूखी रह सकती है। Dedicated capacity running long job को pre-empt नहीं करती; low-priority work भी same database पर contention कर सकता है।
Web और worker compute अलग करना budgets बचा सकता है; containers/cgroups या separate nodes दोनों उचित हो सकते हैं। Shared DB/cache/network failure दोनों को प्रभावित कर सकते हैं। Workers अलग हुए तो pages कभी प्रभावित नहीं होंगे, ऐसा वादा सही नहीं।
Backlog के साथ नई arrivals भी गिनें
तुरंत ready backlog B=1,000 jobs और relevant I/O सहित mean worker-occupied time s=0.12 seconds/job मानें। काम 120 worker-seconds है। New arrivals न हों तो 12 perfectly balanced workers का fluid lower bound 10 seconds है। समान indivisible jobs में भी 84 waves×0.12=10.08 seconds चाहिए; dispatch, skew, retries और contention अतिरिक्त हैं।
अब 50 नए ready jobs/second लगातार आएँ। w workers का ideal throughput w÷0.12 है। यह 50 से अधिक हो तभी backlog घटेगा; ideal drain time B÷(w÷s−50)। Table planning model है, measured benchmark या deadline guarantee नहीं।
इन arrivals पर 10-second target का fluid lower bound w≥s×(50+B÷10)=18 है। Variability, failures और dependencies के लिए tested headroom चाहिए। Job count को runtime से भाग देकर worker count न कहें; units और target horizon ज़रूरी हैं।
Workers
Ideal throughput jobs/s
Net backlog drain jobs/s
1,000 का fluid drain
6
50
0
Net drain नहीं
12
100
50
20 seconds
18
150
100
10 seconds
Workers बढ़ाते हुए shared bottleneck आएगा। Useful completions, oldest eligible-ready age, occupied-time distribution, DB waits, lock contention और provider limits मापें। छोटी ready queue के साथ reserved/stuck jobs बहुत हो सकते हैं; भविष्य के delayed jobs ready alert न बढ़ाएँ।
असल deployment के processes या replicas scale करें
वर्तमान Laravel 13 Horizon guidance simple में process distribution, auto allocation और ordered-queue false mode अलग बताती है; false में भी process count बढ़ सकता है। Auto में array order strict priority नहीं। False को हर version का fixed-pool switch मानने के बजाय installed version देखें।
Horizon Redis workers supervise करता है; वर्तमान docs Redis Cluster बाहर रखते हैं। कई compute nodes पर चल सकता है, पर node provision स्वयं नहीं करता। Queues, supervisors और replicas के minima/maxima तथा resources जोड़ें; एक supervisor का cap पूरे deployment का global limit नहीं।
KEDA 2.21 Kubernetes workloads को event-driven scaling signal दे सकता है, HPA replicas बदलता है। Available compute, polling/metric freshness, activation, image start, readiness और scale-down actual response तय करते हैं। Pods/processes की universal seconds/minutes guarantee नहीं; compute/operation cost भी रहती है।
Driver के सही signal लें। Redis list length ready entries गिने पर reserved/delayed छूट सकते हैं। Known burst से पहले उचित minimum तैयार करें और reactive capacity tested limits में रखें। दूसरा scaling loop पहले से न लड़े।
Timeout, reservation expiry और retry delay अलग घड़ियाँ हैं
काल्पनिक Horizon/Redis timing: external-call deadline 10 seconds, job timeout 45, supervisor 60 और connection retry_after 90 । ये shipped settings नहीं। Horizon timeout job से बड़ा और retry_after से सुरक्षित कम हो; actual driver, runtime extensions तथा termination test करें।
retry_after application retries के बीच delay नहीं। Reserved job सही complete/release न हो तो कब फिर eligible हो सकता है, यह तय करता है। पहला worker चलता रहे और दूसरा job ले ले तो effects दोहर सकते हैं। SQS visibility और अन्य drivers के contracts अलग हैं।
उदाहरण boundary
Seconds
उद्देश्य
External call
10
Actual call सीमित
Job timeout
45
एक execution सीमित
Horizon supervisor timeout
60
Job से ऊपर; reservation expiry से नीचे
Redis retry_after
90
Reservation eligibility, retry backoff नहीं
Attempt/total-age limits, exception/release rules और उपयुक्त backoff/jitter दें। Invalid permission या bad data correction माँगता है, अंतहीन retries नहीं। Failed-job store में alert, owner और reviewed retry/cancel route चाहिए; row लिखना recovery नहीं। Middleware release attempts खा सकता है, वास्तविक semantics देखें।
Effect की सीमा पर duplicate attempt सुरक्षित करें
शुरुआत में already done check दूसरे worker से race या receipt लिखने से पहले crash रोकता नहीं। Local DB effect में scoped unique operation claim, mutation और result एक atomic transaction में रखें। Queue uniqueness या overlap lock external payment/email एक बार होने का प्रमाण नहीं।
Provider call में durable business reference और supported idempotency/status lookup रखें। Stripe idempotency contract key scope, parameters और retention का महत्व दिखाता है। Unknown response पर original query/reconcile करके replacement तय करें; नया key नया charge कर सकता है।
Paid invoice का PDF fail हो तो document recover करें, collection नहीं। Email request acknowledged होना inbox delivery नहीं। Task attempt, provider result और business completion अलग रखें। Replay approved current state माने, सभी dedupe keys साफ़ न करे।
Queue बचे काम का transport है। Retry business operation बचाए और unknown provider result दिखाई देता रहे।
Memory, privacy और deploy recovery साथ budget करें
Resident worker/runtime overhead, retained memory, heavy-job peaks और shared/container base गिनें। उदाहरण 10 workers×128 MiB private/incremental allowance=1,280 MiB=1.25 GiB, अन्य overhead/headroom से पहले। इससे 2 GiB container पर्याप्त नहीं सिद्ध होता। Mixed pools में अपने-अपने worker×memory budget जोड़कर साथ peak test करें।
Streaming/chunking memory घटा सकते हैं पर libraries buffer कर सकती हैं; splitting ordering/recovery बदलती है। बनाया 288→128 MiB saving नहीं, before/after मापें। उचित रूप से long-lived workers recycle करें। Evidence बिना RAM/workers बढ़ाने से असली bottleneck रह सकता है।
Minimum scoped data दें; ID स्थायी record-fetch permission नहीं। Owning service authority/state फिर जाँचे। Broker transport/storage, payloads, failures, dashboards और exports बचाएँ। Payload encryption सभी metadata/logs नहीं बचाती। OWASP logging guidance secrets या salary/customer documents डाले बिना उपयोगी evidence रखने का आधार है।
Compatible code/schema/payloads deploy करें और supervised long-running workers gracefully बदलें। पूरी queue खाली करना ज़रूरी नहीं। Tested termination/visibility limits में current work पूरा या safe recover हो; old work संभलने तक compatibility रहे। Scheduler आख़िर शुरू करना अकेले incompatible jobs या duplicate schedule नहीं ठीक करता।
Queue को दिखाई देने वाली obligations की तरह चलाएँ
Laravel scheduler guidance shared atomic locks से coordinated single-server work देती है; fixed cron node एकमात्र topology नहीं। Expiry, overlap, failover और missed runs को business idempotency के साथ test करें। Periodic relay वैध हो सकता है; long-lived process हर memory problem का इलाज नहीं।
Commit से पहले/बाद crash, publish failure, concurrent duplicate, unknown timeout, bad payload, revoked access, heavy peak और mid-job deploy rehearse करें। Real external charges/messages अलग रखें। Same scope/time/state के pending obligations और actual effects मिलाएँ, केवल queue depth zero नहीं।
उपयोगी 9 बजे dashboard बताता है answers received, grading pending/completed, notifications accepted/confirmed और exceptions किसके हैं। Exact target integrated test माँगता है। StoreConsole सहित supplier से offered version/modules में path, permissions और bounded recovery दिखवाएँ।



 सॉफ़्टवेयर आर्किटेक्चर

